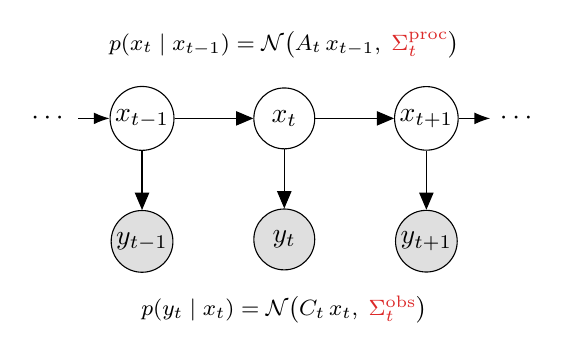
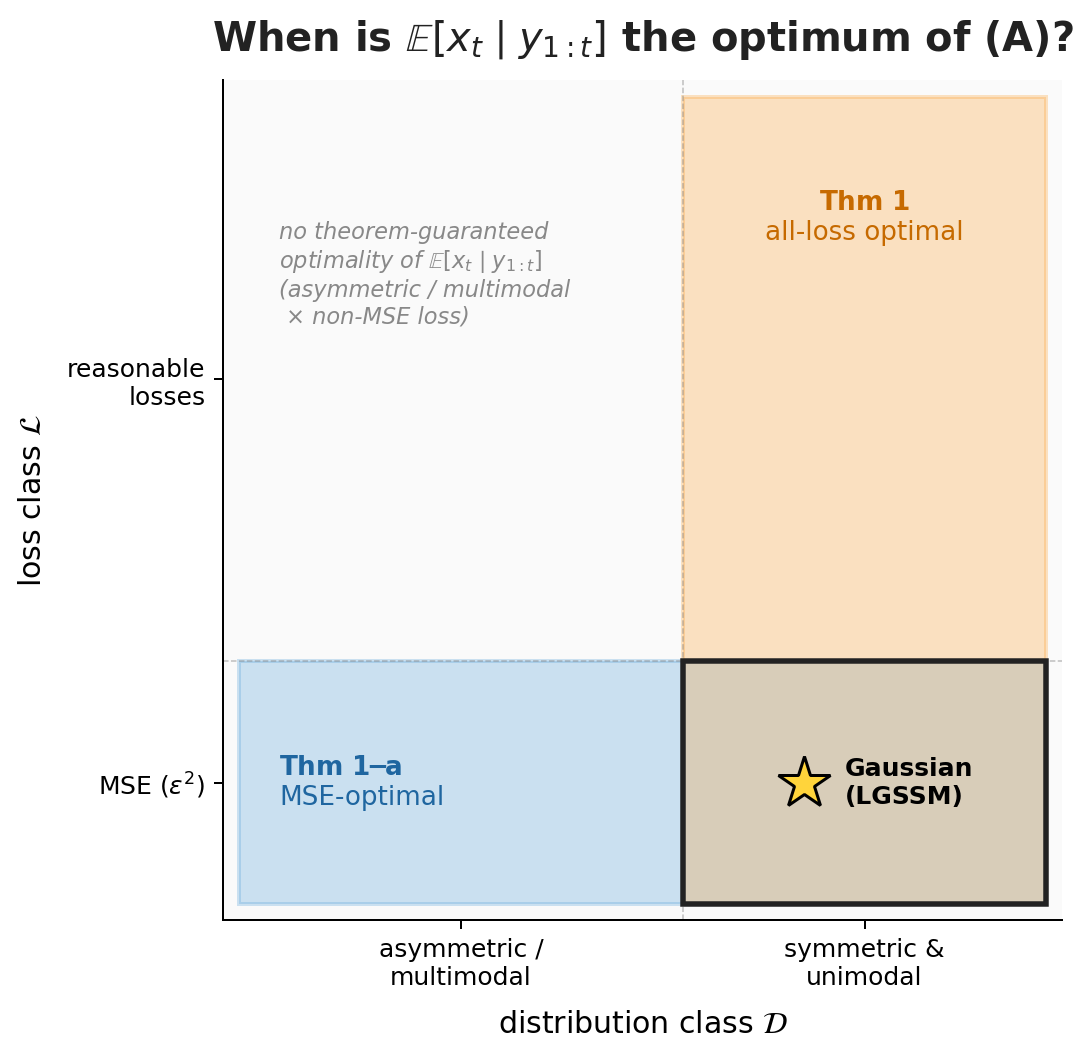
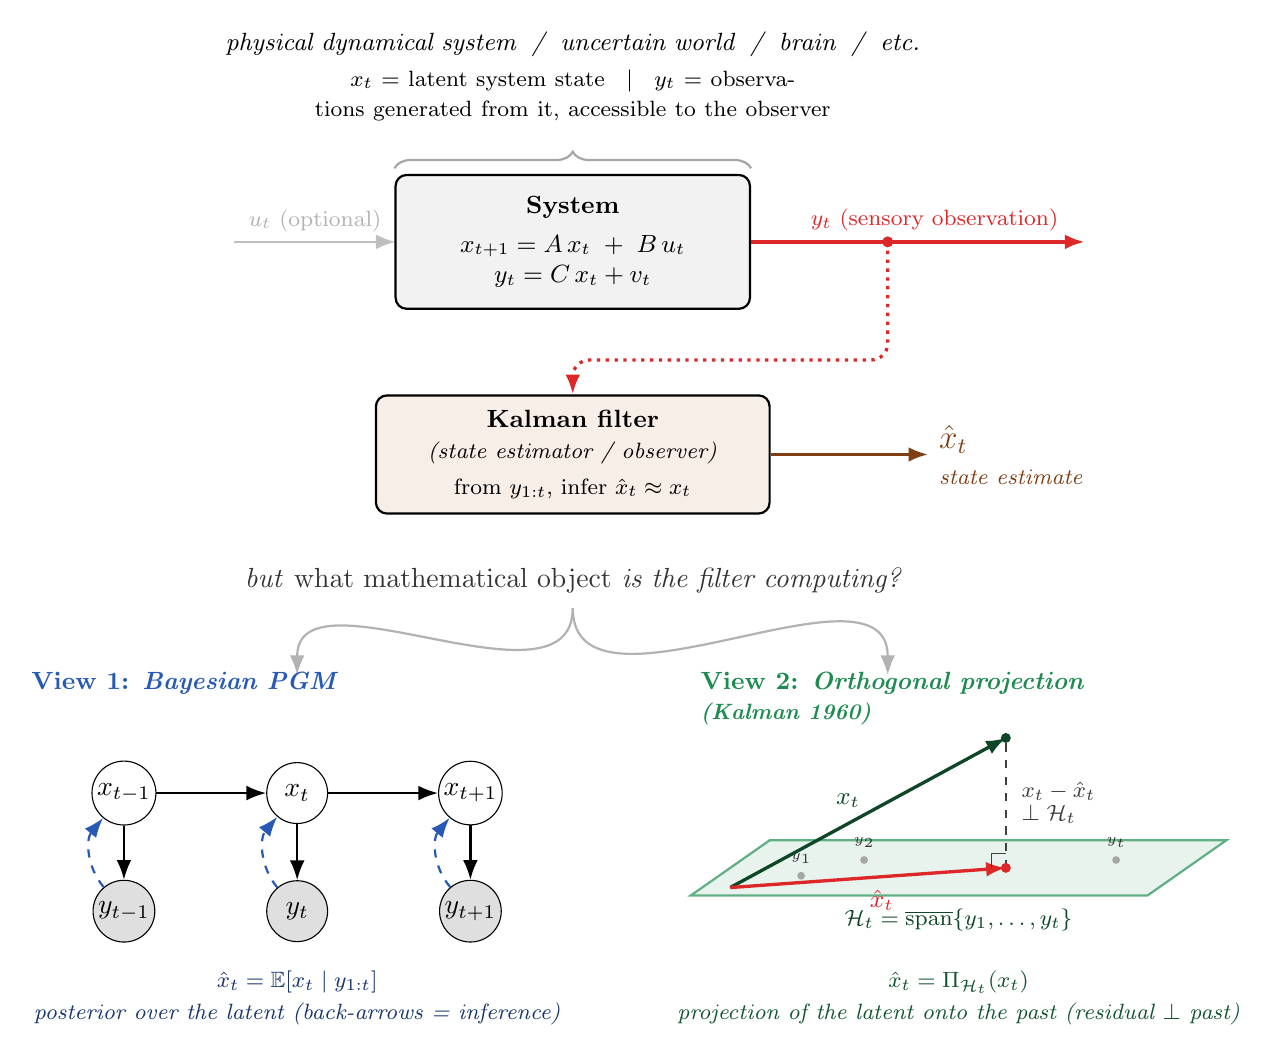
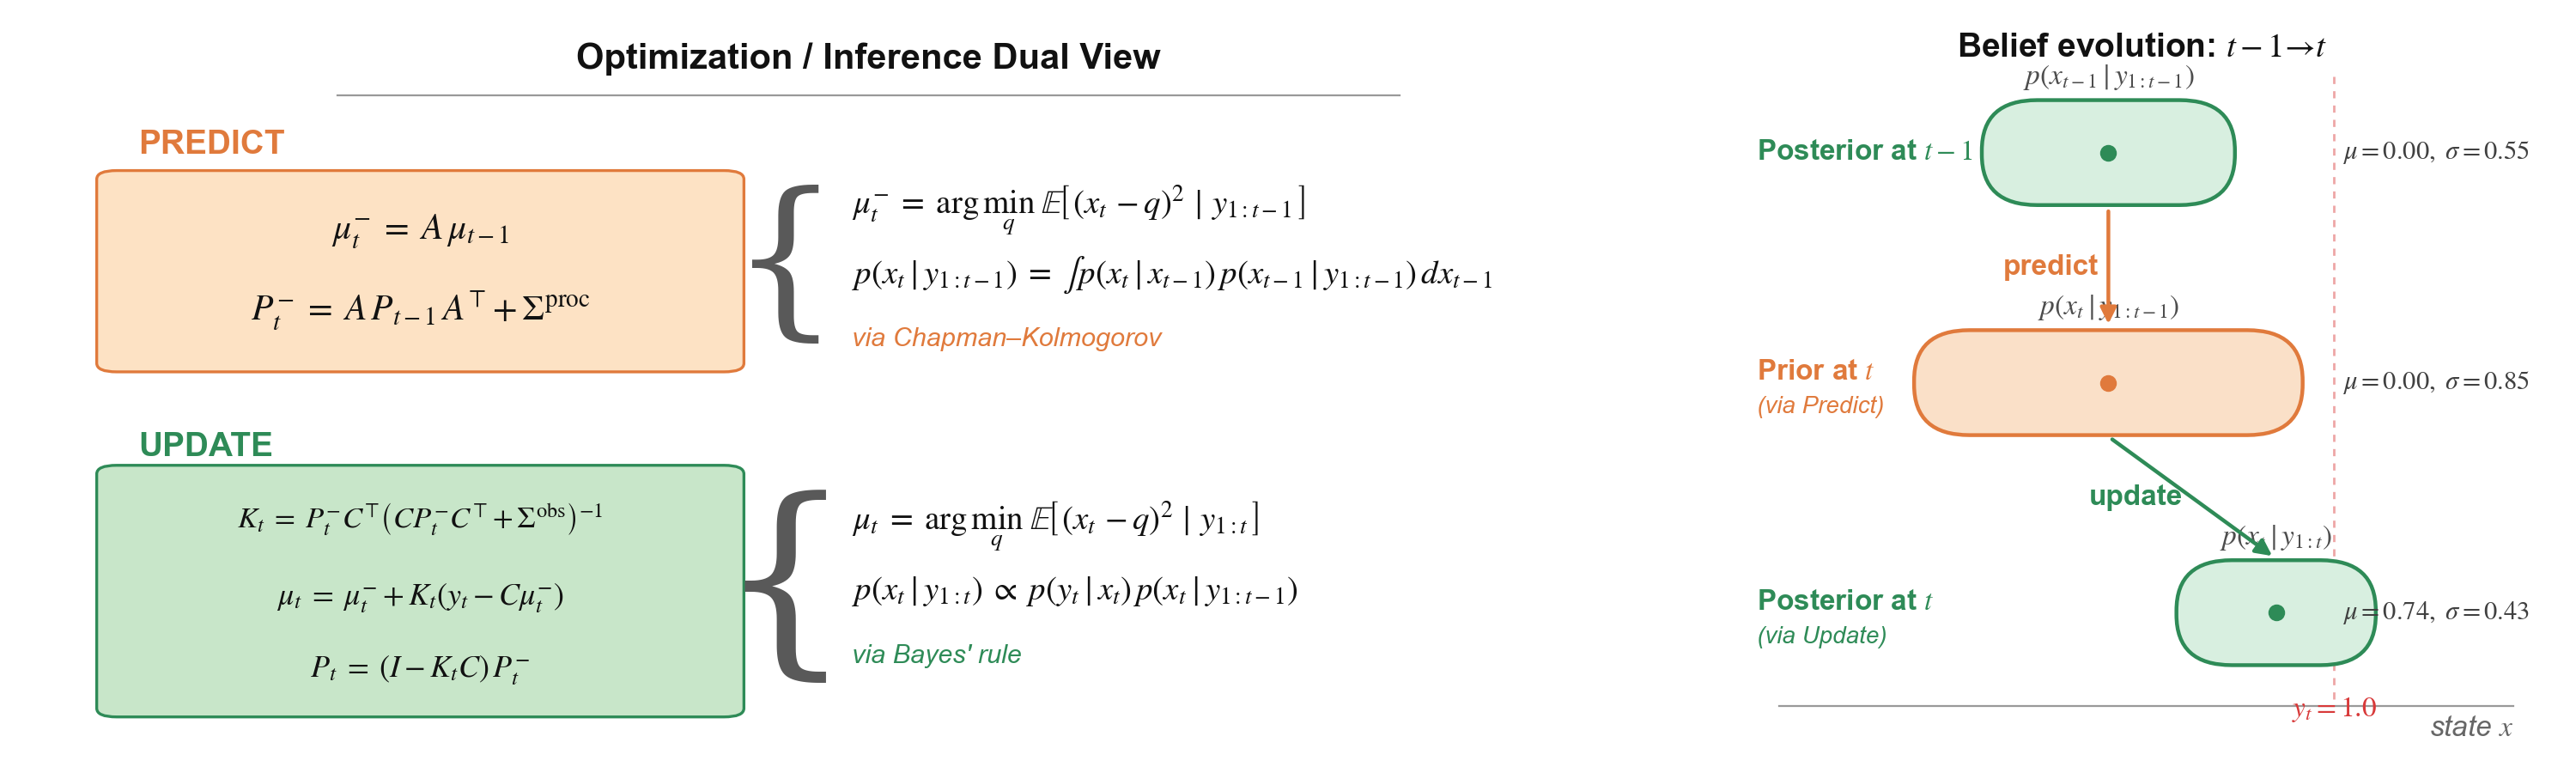
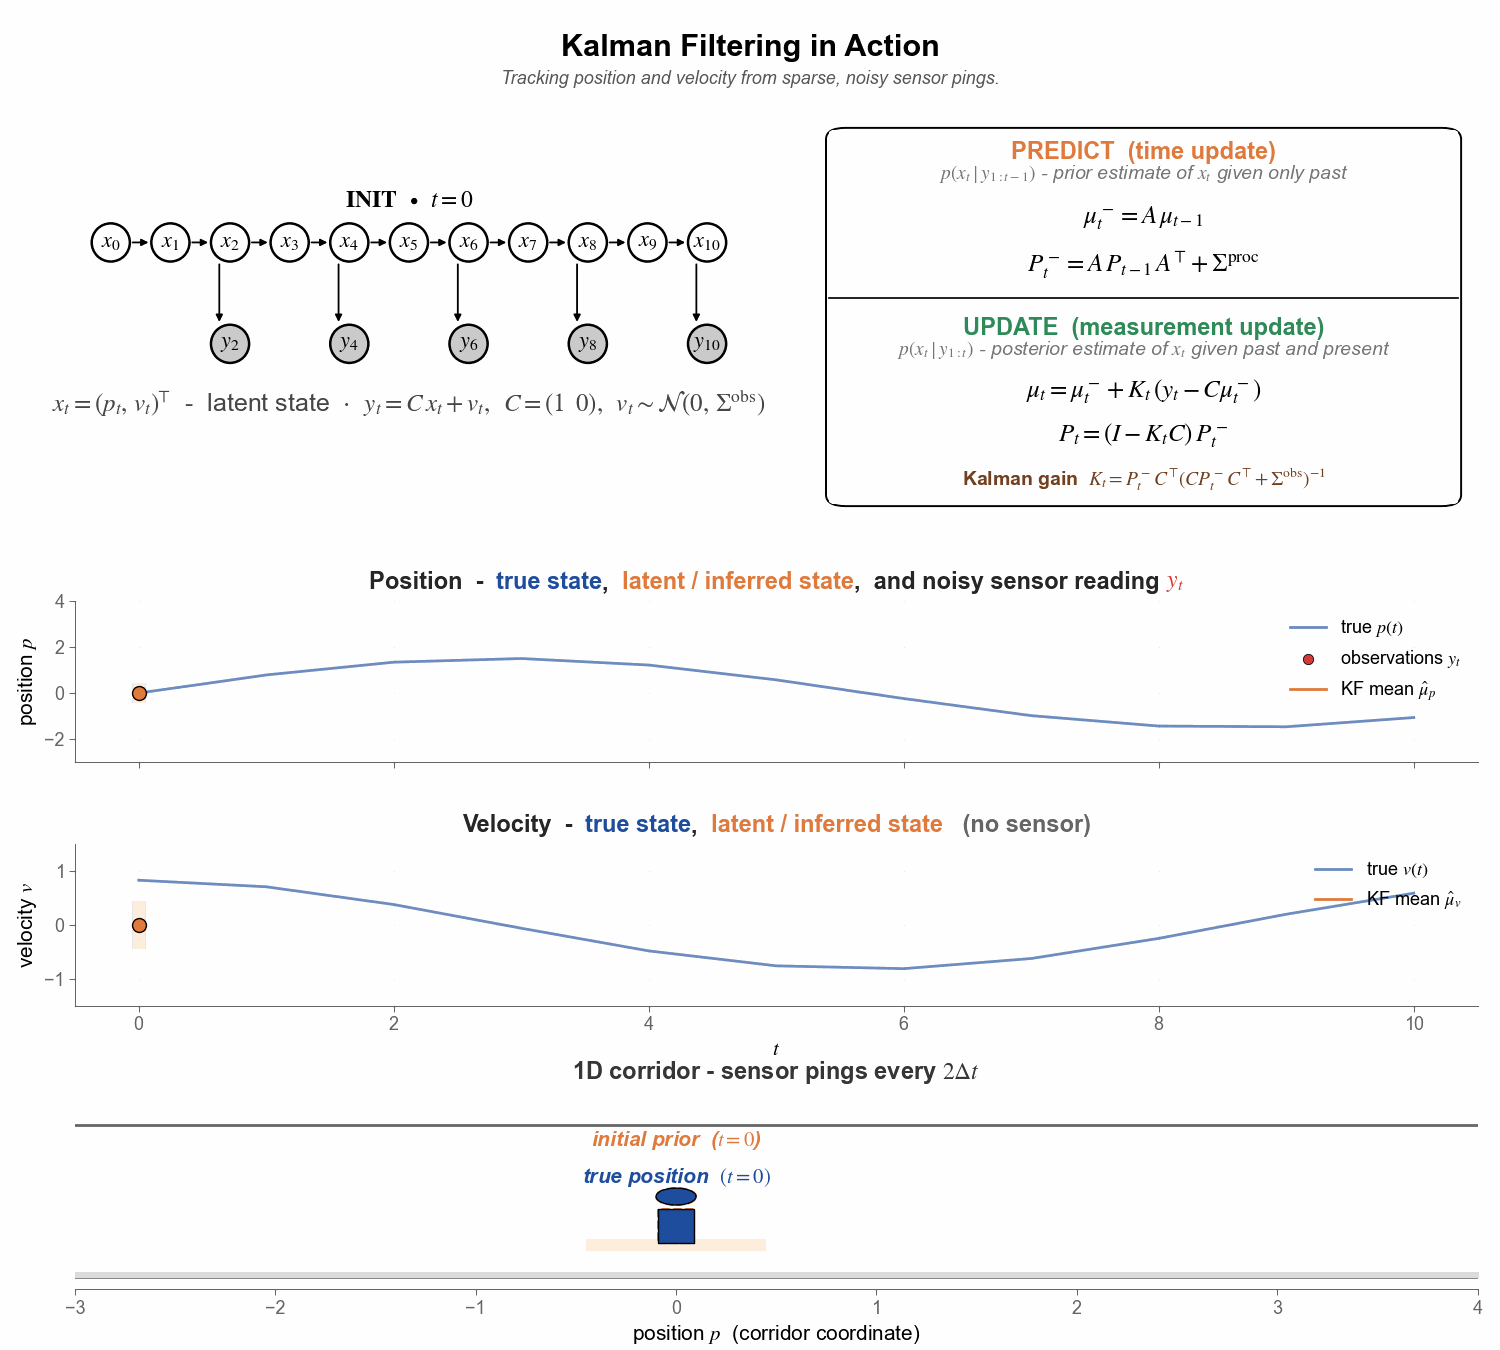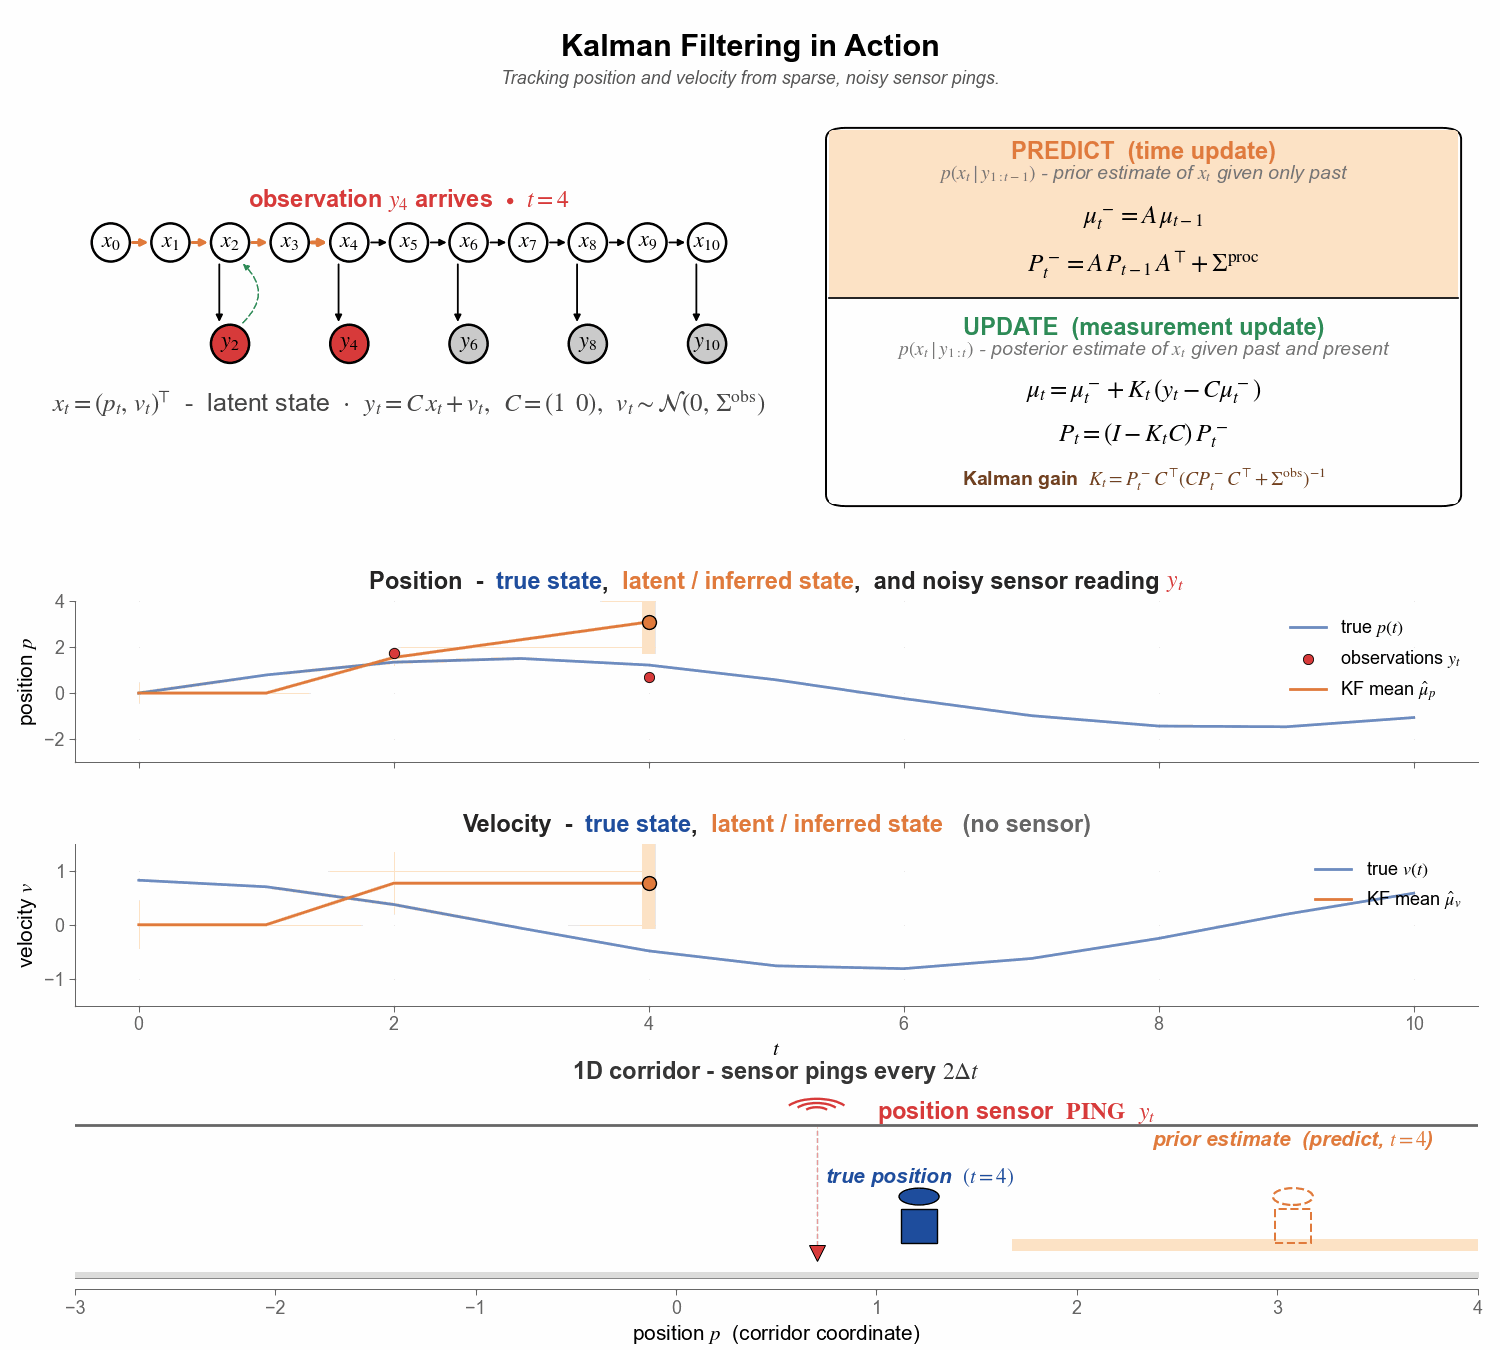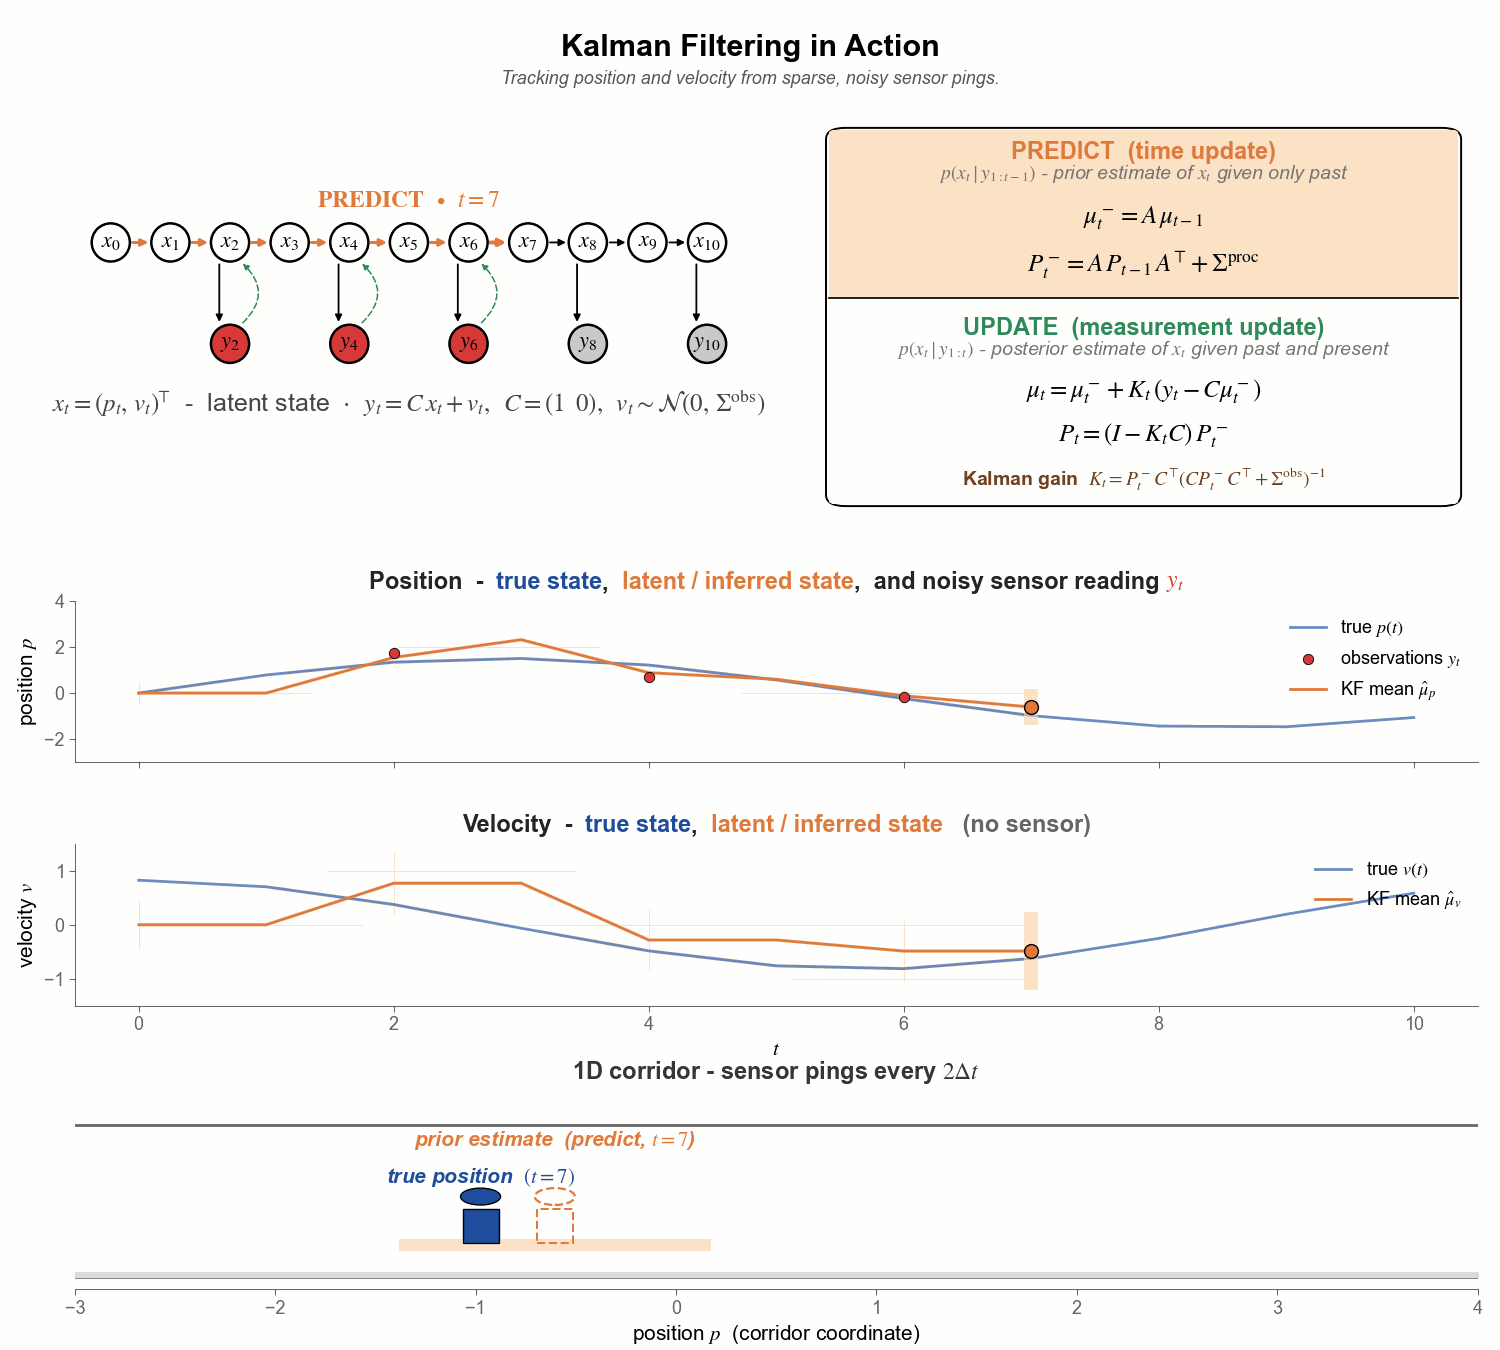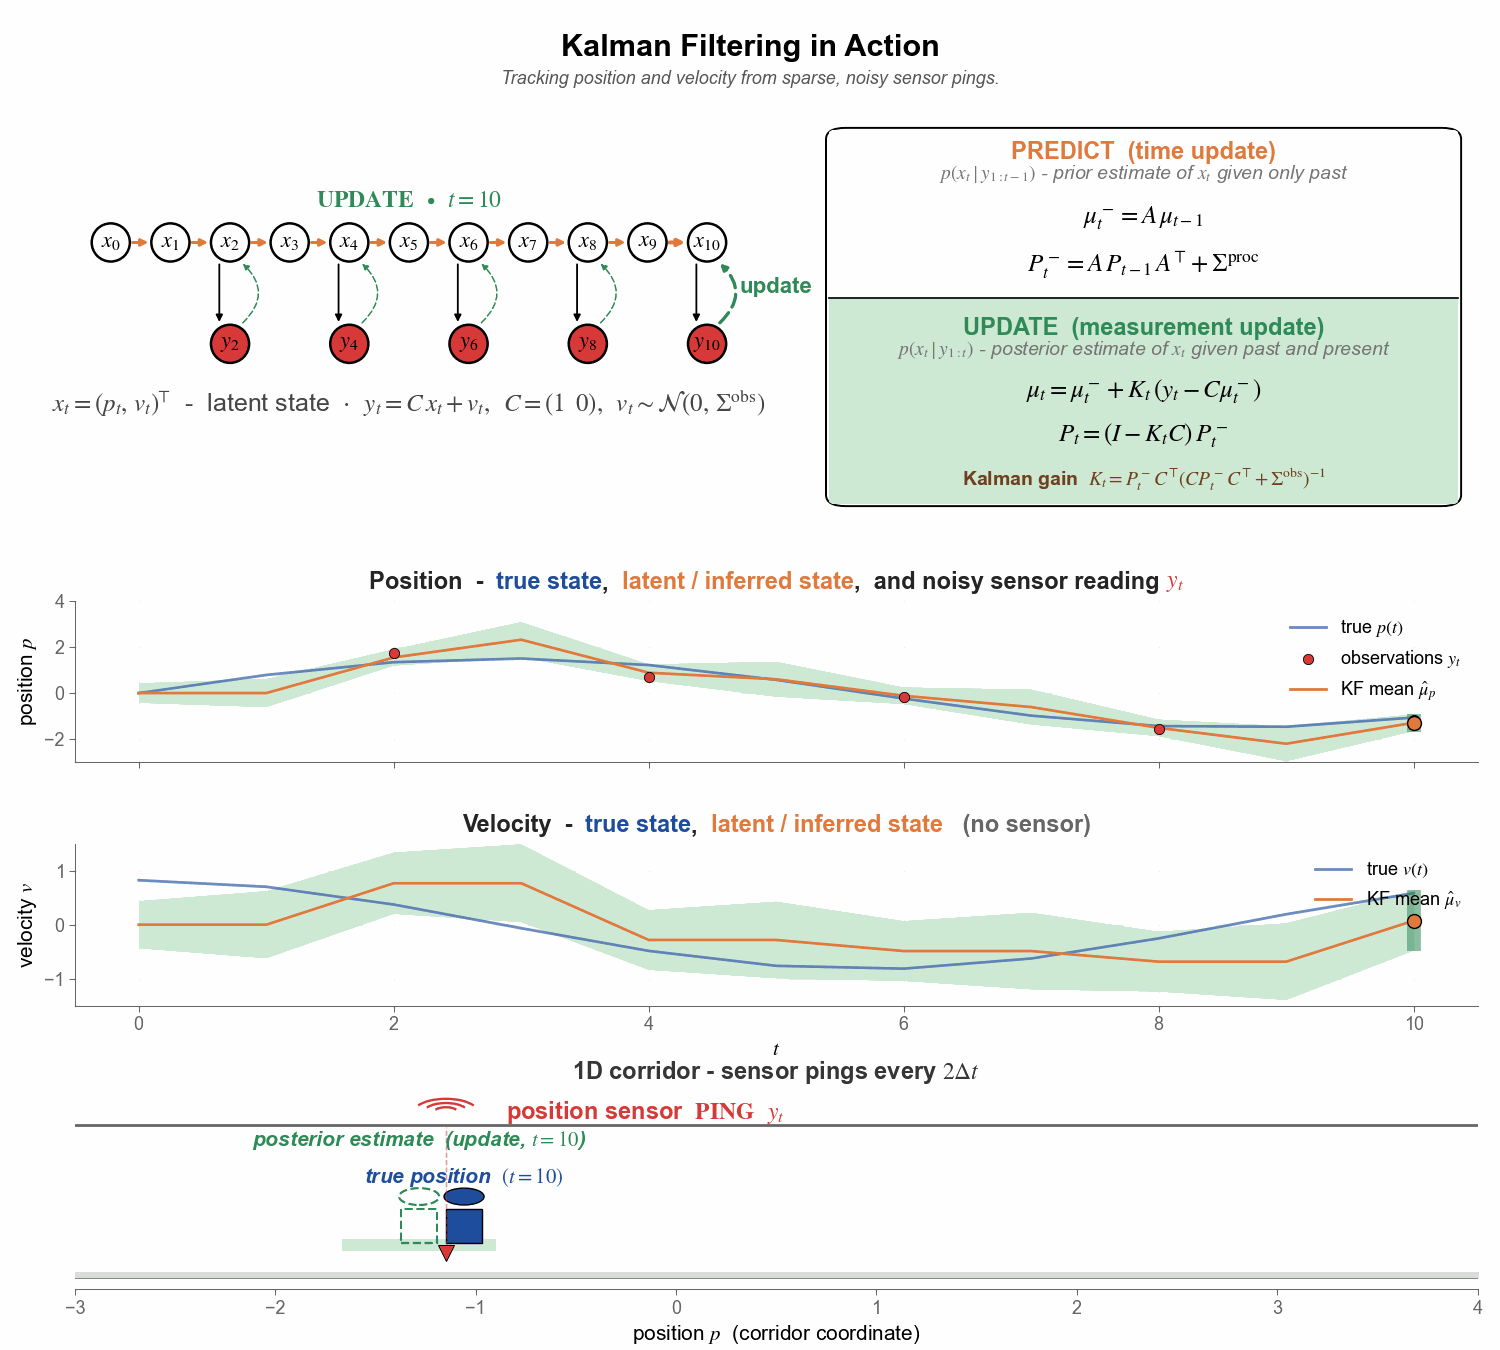
<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://vaisakh-shaj.github.io/feed.xml" rel="self" type="application/atom+xml"/><link href="https://vaisakh-shaj.github.io/" rel="alternate" type="text/html" hreflang="en"/><updated>2026-05-18T12:00:14+00:00</updated><id>https://vaisakh-shaj.github.io/feed.xml</id><title type="html">blank</title><subtitle>A simple, whitespace theme for academics. Based on [*folio](https://github.com/bogoli/-folio) design. </subtitle><entry><title type="html">Kalman Linear Attention 1: A Beginner’s Guide to Kalman Filters</title><link href="https://vaisakh-shaj.github.io/blog/2026/KLA_1/" rel="alternate" type="text/html" title="Kalman Linear Attention 1: A Beginner’s Guide to Kalman Filters"/><published>2026-03-10T00:00:00+00:00</published><updated>2026-03-10T00:00:00+00:00</updated><id>https://vaisakh-shaj.github.io/blog/2026/KLA_1</id><content type="html" xml:base="https://vaisakh-shaj.github.io/blog/2026/KLA_1/"><![CDATA[<p><em>Part 1 of a series connecting classical Bayesian filters to modern linear-attention sequence models.</em></p> <p>What if I told you that the same recursive algorithm that steered <a href="https://aerospaceamerica.aiaa.org/departments/honoring-a-legacy-algorithm/"><strong>Apollo 11 to the moon</strong></a>, that helps neuroscientists <a href="https://www.sciencedirect.com/science/article/pii/S004269899800279X"><strong>decode signals from the visual cortex</strong></a>, and that runs inside every <strong>smartphone GPS</strong> - is, with a one-line reparameterisation, a <strong>linear-attention layer</strong> for modern sequence models?</p> <p>That algorithm is the <strong>Kalman filter</strong>: sixty-five years old, trusted everywhere engineers need to <em>infer the hidden state of a noisy world from partial observations of it</em>. This three-part series shows how it becomes <strong>Kalman Linear Attention (KLA)</strong><d-cite key="shaj2026kalman"></d-cite> — a drop-in replacement for softmax attention with linear-time inference, parallel training, and calibrated uncertainty <em>for free</em>.</p> <p>This first post is the filter itself: the minimum working mental model — no prerequisites beyond basic linear algebra and probability. <strong>Already fluent in predict-update?</strong> Skip ahead to <strong>Part 2</strong>, where the same recursion turns into an attention layer.</p> <blockquote> <p><strong>The journey.</strong> §1 builds intuition · §2 sets up the stochastic SSM in which filtering / state estimation is performed · §3 states the problem the KF solves · §4 <em>when and why is it the “best” of all estimators?</em> :) · §5 sketches the derivation of the recursion · §6 watches one work on a James Bond 🕶️ scenario · §7 points to further references.</p> </blockquote> <hr/> <h2 id="1-what-is-a-kalman-filter">1. What Is a Kalman Filter?</h2> <table> <tr> <td width="50%" valign="top"> <blockquote> <p>A Kalman filter is a <a href="https://en.wikipedia.org/wiki/State_observer"><strong>state observer</strong></a> / estimator - a recursive estimator that infers the <strong>latent state</strong> <em>(the hidden quantities the world keeps from you)</em> of a (stochastic) black-box physical system from a stream of <em>noisy</em>, <em>partial</em> observations of it.</p> </blockquote> <p>The eye in <strong>Figure 1</strong> is more than a metaphor: mathematically, a <a href="https://en.wikipedia.org/wiki/State_observer">state observer / estimator</a> is a piece of code that consumes observations $y_{1:t}$ and produces an estimate $\hat x_t$ of <em>“what the world looks like, given what I’ve seen so far”</em>. The Kalman filter is one specific - and very famous - observer: the <strong>optimal linear</strong> one for a particular class of models.</p> </td> <td width="50%" valign="top" align="center"> <img src="/assets/img/kla_part1/observer_figure.gif" alt="Unknown system + state observer schematic (animated). Top: a (stochastic) physical / black-box world - the rotating globe stands in for the unknown system whose hidden state x_t evolves as x_{t+1} = f(x_t, u_t) + ω_t and emits noisy observations y_t=g(x_t) + γ_t streaming down the y_t arrow. Bottom: a state observer / estimator (here: a Kalman filter, drawn with an eye icon) that consumes y_{1:t} and produces x̂_t plus an uncertainty estimate P_t." width="100%"/> <br/><br/> <sub><em><strong>Figure 1.</strong> The <b>unknown system + observer</b> frame the rest of the post lives in.<br/> The top box is the world - possibly non-linear, possibly stochastic,<br/> with hidden state $x_t$. The bottom box is the observer (the eye is<br/> its job: looking at the world through the only window it has, $y_t$).<br/> The Kalman filter is the <b>specific</b> observer we'll build.</em></sub> </td> </tr> </table> <p>The KF’s inference equations are derived from a particular <em>linear</em> choice for the system functions $f$ and $g$ above, and a <em>Gaussian white-noise</em> assumption (sometimes weaker - see below). We’ll lay out that model in <strong>§2</strong> next.</p> <hr/> <h2 id="2-linear-noisy-state-space-models">2. Linear Noisy State-Space Models</h2> <p>We have an unknown system and want to <strong>infer its underlying state</strong> in real time from a stream of observations. To get anywhere we have to commit to a <strong>simplified generative model</strong> of how the world produces those observations - with the simplifications chosen so that</p> <ol> <li><strong>inference is tractable in real time</strong> for the use case (constant compute and memory per step), and</li> <li>the <strong>modelling errors and uncertainties</strong> introduced by those simplifications are absorbed into explicit noise terms - so the filter always knows what it doesn’t know.</li> </ol> <p>Concretely, the Kalman filter’s simplification is exactly the one previewed at the end of <strong>§1</strong>: take the transition and observation functions $f, g$ to be <strong>linear</strong>, and let the noise terms $\omega_t, \gamma_t$ absorb every unmodelled effect. Spelled out, that gives the following <strong>linear state-space generative model</strong>.</p> <table class="l-body-outset"> <tr> <td width="58%" valign="top"> <p><strong>1. Linear dynamics.</strong> The latent state evolves linearly in time:</p> \[x_{t+1} \;=\; A_t\, x_t \;+\; B_t\, u_t \tag{2.1}\] <p>where $u_t$ is an <em>optional</em> control input. In unactuated settings - the most relevant for language modelling used in KLA<d-footnote>KLA = Kalman Linear Attention, the technique built in Part 2 - a Kalman recursion wrapped in a deep encoder with all four matrices learned.</d-footnote> - $B_t u_t$ is absent.</p> <p><strong>2. Process noise</strong> ($\omega_t$) absorbs everything else (mild non-linearities, model errors, external disturbances):</p> \[x_{t+1} \;=\; A_t\, x_t \;+\; B_t\, u_t \;+\; \omega_t \tag{2.2}\] <p><strong>3. Linear observation model.</strong> What you see is a linear function of the state:</p> \[y_t \;=\; C_t\, x_t \tag{2.3}\] <p><strong>4. Observation noise</strong> ($\gamma_t$). Sensors are noisy - same trick:</p> \[y_t \;=\; C_t\, x_t \;+\; \gamma_t \tag{2.4}\] <p><strong>5. White noise.</strong> $\omega_t$ and $\gamma_t$ are zero-mean, uncorrelated across time, with finite (constant) covariance:</p> \[\Sigma^{\mathrm{proc}} = \mathbb{E}\!\left[\omega_t \omega_t^{\top}\right], \quad \Sigma^{\mathrm{obs}} = \mathbb{E}\!\left[\gamma_t \gamma_t^{\top}\right] \tag{2.5}\] </td> <td width="42%" valign="top" align="center"> <img src="/assets/img/kla_part1/lgssm_pgm.png" alt="Linear noisy state-space model as a graphical model. A hidden chain of latents x_{t-1}, x_t, x_{t+1} (with continuation dots on either side) where each latent emits a noisy observation y_t below it. The Gaussian transition and emission conditionals are written above and below the chain, with the noise covariances highlighted in red." width="100%"/> <br/><br/> <sub><em><strong>Figure 2.</strong> The five assumptions drawn as a graphical model.<br/> Latents $x_t$ form a hidden chain (top); each emits a noisy<br/> observation $y_t$ (bottom). Shown is the <strong>Gaussian special case</strong> - the typical textbook form. Under just white noise (per the callout below), the same equations describe only the <strong>first two moments</strong> of the conditionals.</em></sub> </td> </tr> </table> <blockquote> <p><strong>🟦 On the Myth of Gaussianity Being Necessary.</strong> Notice that Gaussianity was nowhere on the assumption list above - that absence is deliberate, not an oversight. The PGM in <strong>Figure 2</strong> draws the Gaussian special case only because it makes the textbook <em>Bayesian</em> derivation closed-form; Kalman’s 1960 derivation itself never requires it. Two precise takeaways:</p> <ol> <li><strong>Gaussianity isn’t needed to <em>write down or run</em> the Kalman recursion.</strong> Kalman’s derivation leaves $p(x_t \mid x_{t-1})$ and $p(y_t \mid x_t)$ as arbitrary, unspecified distributions and characterises them <em>only</em> through their first two conditional moments - the conditional expectations $\mathbb{E}[x_t \mid x_{t-1}] = A_t x_{t-1}$, $\mathbb{E}[y_t \mid x_t] = C_t x_t$ and the conditional covariances $\mathrm{Cov}[x_t \mid x_{t-1}] = \Sigma^{\mathrm{proc}}_t$, $\mathrm{Cov}[y_t \mid x_t] = \Sigma^{\mathrm{obs}}_t$ - with the densities $p(\,\cdot \mid \cdot\,)$ themselves never committed to a parametric form. The closed-form recursive estimator is derived from these alone, via optimisation - no Gaussian density ever invoked.</li> <li><strong>Gaussianity <em>sharpens</em> the optimality claim - it doesn’t unlock the algorithm.</strong> <em>Without</em> it, the recursion is the best <em>linear</em>-MSE estimator (no linear estimator beats it; nonlinear ones in principle could). <em>With</em> Gaussianity - or just symmetry+unimodality of the posterior - the <em>same equations</em> deliver the true conditional mean $\mathbb{E}[x_t \mid y_{1:t}]$, which is the best estimator among <em>all</em> reasonable estimators under MSE. Same equations, strictly stronger guarantee. Kalman 1960 lays out the full hierarchy of optimality theorems spanning these (loss, distribution) regimes; we work through them in <strong>§4</strong>.</li> </ol> </blockquote> <h3 id="21-is-the-linear-assumption-too-restrictive">2.1. Is the Linear Assumption Too Restrictive?</h3> <p>Looking at that list it’s tempting to say <em>“linear dynamics + linear observations? My problem isn’t like that at all.”</em> In practice the filter is <strong>surprisingly robust</strong> for two reasons.</p> <ol> <li> <p><strong>The noise term is a load-bearing fudge factor.</strong> Anything you didn’t model - slow drifts, sensor biases, mild non-linearities - gets absorbed into $\omega_t$ and $\gamma_t$. The covariances $\Sigma^{\mathrm{proc}}$ and $\Sigma^{\mathrm{obs}}$ are <em>tuning knobs</em> that tell the filter how much to trust its dynamics versus its sensors.</p> </li> <li> <p><strong>A wrong-but-good-enough model with reasonable noise estimates can still produce excellent state estimates</strong> - online, recursively, in constant memory. The filter doesn’t need to be the truth; it needs to be useful.</p> </li> </ol> <p>If you want <em>richer</em> expressivity - non-linear latent dynamics, learned features, hierarchical structure - replace the handcrafted matrices with neural networks: process incoming sensory signals through a neural feature extractor and do filtering in a non-linear latent space. We’ll explore that path in <strong>Part 2</strong>: from the linear KF to <em>Kalman Linear Attention</em> (KLA)<d-cite key="shaj2026kalman"></d-cite>.</p> <hr/> <h2 id="3-toward-the-kf-update-equations-state-estimation-via-optimization-and-its-inference-dual">3. Toward the KF Update Equations: State Estimation via Optimization (and its Inference Dual)</h2> <p><em>Earlier we framed the KF as a <strong>state observer</strong> - a black-box consumer of $y_{1:t}$ that emits a state estimate $\hat x_t$. But <strong>how does that estimation actually work?</strong></em> The KF update equations can be seen as solutions to <strong>one well-posed problem with two equivalent statements</strong>: either <em>(i)</em> solving an <strong>optimisation objective</strong> with a specific loss $L$, or <em>(ii)</em> doing <strong>probabilistic inference</strong> on a specific directed graphical model - the <strong>Linear Gaussian State Space Model (<abbr title="Linear Gaussian State Space Model">LGSSM</abbr>)</strong> PGM drawn earlier (<strong>Figure 2</strong>, the <em>Five Assumptions</em> graphical model). We write both statements here. <strong>§5</strong> walks through how the recursion is derived from either one (optional reading), and <strong>§5.1 (The Predict–Update Cycle)</strong> shows what the recursion does at each step.</p> <p><strong>Statement A - optimisation.</strong> Given $y_{1:t}$, find the estimator that minimises an expected loss</p> \[\hat x_t \;=\; \arg\min_{\hat{x}}\; \mathbb{E}\!\left[\,L(x_t - \hat{x}) \,\big|\, y_{1:t}\,\right]. \tag{3.1}\] <p><strong>Statement B - inference (the dual).</strong> Given the same $y_{1:t}$, compute the posterior over the latent state</p> \[p(x_t \,\big|\, y_{1:t}), \tag{3.2}\] <p>and report a summary of it - by default, its mean.</p> <blockquote> <p><strong>🟦 (A) and (B) Coincide on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> but importantly not the only case where this can coincide.</strong> Kalman 1960<d-cite key="kalman1960new"></d-cite> pins down the precise conditions under which the optimisation statement (3.1) and the inference statement (3.2) yield the same answer - illustrated in <strong>Figure 3</strong>, with the broader duality map detailed in the toggle below (optional).</p> </blockquote> <blockquote> <p><strong>🟦 The Take-Away for the Rest of This Post.</strong> The (A) ↔ (B) duality isn’t a hand-wavy observation - Kalman 1960 establishes it rigorously via a small <em>hierarchy of optimality theorems</em> (Thm 1, 1-a, 2 - laid out in <strong>§4</strong>) that hold across surprisingly general regimes of loss and distribution. A practical consequence: because the two sides of the duality provably coincide, the <em>same</em> Kalman recursion can be re-derived from the native toolkit of whichever field one is most fluent in - <em>optimisation</em> (orthogonal projection in $L^2$<d-footnote>$L^2$ is the Hilbert space of square-integrable random variables - random variables $X$ with $\mathbb{E}[X^2] &lt; \infty$ - equipped with inner product $\langle X, Y \rangle = \mathbb{E}[XY]$ and norm $\|X\| = \sqrt{\mathbb{E}[X^2]}$. The norm-squared is precisely the MSE, so minimising MSE = minimising squared distance in $L^2$, and the best linear estimator is the orthogonal projection of $x_t$ onto the linear span of past observations $\{y_1, \ldots, y_t\} \subset L^2$. Not to be confused with $\ell_2$ (lowercase $\ell$), which in ML usually refers to finite-dimensional weight regularisation / squared loss.</d-footnote>), <em>probabilistic inference / graphical models</em> (message passing on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> PGM similar to HMMs), <em>information geometry</em> (KL projection onto a Gaussian manifold), and so on. In every case the target object is the same: $\mathbb{E}[x_t \mid y_{1:t}]$.</p> </blockquote> <details> <summary><strong>(Optional / Advanced) Mapping the (A. Optimization) ↔ (B.Inference) duality region - where does the Kalman recursion live? →</strong></summary> <p><strong>The precise duality conditions.</strong> Kalman 1960<d-cite key="kalman1960new"></d-cite> lays this out in two theorems: under MSE, <em>no distributional assumption on the posterior is needed</em> (<strong>Thm 1-a</strong>); under broader losses, <em>symmetry+unimodality of the posterior</em> suffices (<strong>Thm 1</strong>). Spelling out the equality:</p> \[\underbrace{\arg\min_{\hat{x}}\;\mathbb{E}\!\left[\,L(x_t-\hat{x}) \,\big|\, y_{1:t}\,\right]}_{\text{optimum of (A)}}\;\;=\;\;\underbrace{\mathbb{E}\!\left[\,x_t \,\big|\, y_{1:t}\,\right]}_{\text{mean of (B)}} \tag{3.3}\] <p>holds in two cases (<strong>Figure 3</strong> below):</p> <ul> <li><strong>Squared-loss case</strong> <em>(Thm 1-a<d-cite key="kalman1960new"></d-cite>).</em> For $L(\varepsilon)=\varepsilon^{2}$ (MSE), the equality holds <strong>for any distribution</strong> - no symmetry or unimodality needed. $\mathbb{E}[x_t \mid y_{1:t}]$ is simply the $L^{2}$-projection of $x_t$ onto the observations.</li> <li><strong>General-loss case</strong> <em>(Thm 1<d-cite key="kalman1960new"></d-cite>).</em> For <em>any</em> “reasonable” loss $L$ - symmetric, non-decreasing in $\lvert\varepsilon\rvert$, e.g., $\lvert\varepsilon\rvert$, $\varepsilon^{4}$, $1-e^{-\varepsilon^{2}}$ - the equality holds <strong>provided the posterior is symmetric and unimodal</strong>. <em>Gaussian is the canonical instance</em> (symmetric and unimodal by construction), and the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> gives us this for free.</li> </ul> <div align="center"> <img src="/assets/img/kla_part1/optimality_strips.png" alt="Two perpendicular strips in the (loss class, distribution class) plane. Horizontal strip at the MSE row spans all distributions (Thm 1-a). Vertical strip at the sym+uni column spans all reasonable losses (Thm 1). They cross at MSE × sym+uni where both theorems apply; a Gaussian dot inside the intersection cell is labelled 'LGSSM'." style="max-width:100%; height:auto;"/> <br/> <sub><em><strong>Figure 3.</strong> Each Kalman 1960 theorem picks out a rectangle in the $(\mathcal{L}, \mathcal{D})$ plane on which $\mathbb{E}[x_t \mid y_{1:t}]$ is the optimum of (A).<br/> <strong>Thm 1-a</strong> = horizontal strip (MSE $\times$ any distribution); <strong>Thm 1</strong> = vertical strip (any reasonable loss $\times$ sym+uni).<br/> They cross at MSE $\times$ sym+uni - Thm 1's stronger all-loss claim dominates there.<br/> <strong>Gaussian</strong> (and hence the <strong>LGSSM</strong>) lives in the intersection.</em></sub> </div> <p><strong>Where the Kalman recursion sits on this map.</strong> The recursion we derive in <strong>§5</strong> is constrained to the <strong><abbr title="Linear Gaussian State Space Model">LGSSM</abbr> corner</strong>: linear dynamics $+$ linear observations $+$ MSE loss $+$ Gaussian (or just sym+uni) noise. That corner sits inside the <strong>intersection cell</strong> of the strips diagram - both theorems apply, and the conditional mean is optimal under any reasonable loss. The wider map matters because it tells us the duality (A) ↔ (B) holds <strong>far beyond</strong> the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> corner - but practical, <em>recursive</em>, <em>closed-form</em> algorithms only exist inside it. KLA in Part 2 will be a controlled departure from the corner, via data-dependent dynamics.</p> <p><strong>Why the dual view is useful.</strong> Holding (A) and (B) as two faces of the same problem matters chiefly when you want to <strong>derive the recursion from scratch</strong> (as sketched in <strong>§5</strong>) - different techniques (loss-minimization, posterior-update, orthogonal projection) start from different sides of the duality and land on the same equations. For just <em>using</em> the recursion, the intuition alone is enough: state estimation can be cast either way, and the two views coincide on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr>.</p> </details> <hr/> <h2 id="4-best-linear-estimator-under-mse-loss">4. Best Linear Estimator under MSE Loss</h2> <p>Suppose we restrict ourselves to <strong>linear estimators</strong> - i.e. estimators that are a linear function of past observations $(y_{1:t})$,</p> \[\hat x_t \;=\; \sum_{s \,\leq\, t} \alpha_s\, y_s, \tag{4.1}\] <p>where each $\alpha_s$ is a <strong>real-valued (matrix-valued in general) coefficient</strong> applied to past observation $y_s$ - one matrix per time index. The $\alpha_s$ aren’t fixed in advance; they are <strong>picked by the estimator / optimisation algorithm itself</strong>, as whatever values minimise the optimisation objective in <strong>eq (3.1)</strong> - equivalently, whatever values realise the inference summary in <strong>eq (3.2)</strong>. Theorem 2 below then <em>characterises</em> that optimal pick - it turns out to coincide with the orthogonal-projection coefficients (see the toggle).</p> <p>Kalman’s <strong>Theorem 2</strong><d-cite key="kalman1960new"></d-cite> says that, <em>within this class of linear estimators</em>, the optimum under squared (MSE) loss is achieved by the Kalman recursion - and, crucially, <strong>no distributional assumption</strong> on the noise processes $\omega_t, \gamma_t$ is needed for this to hold. Just second moments. No Gaussianity, no symmetry, no unimodality. The Kalman filter is therefore the <strong>gold-standard linear-MSE estimator</strong> for any linear state-space model: nonlinear estimators (particle filters, nonlinear smoothers) can in principle do better, but no <em>linear</em> one can.</p> <details> <summary><strong>(Optional) Why this matters operationally - orthogonal projection, recursivity, and the Apollo connection →</strong></summary> <p><strong>The geometric form.</strong> Theorem 2 says <em>more</em> than “an optimum exists” - it gives that optimum a concrete <strong>geometric form</strong>. The optimal linear estimate <d-math>\hat x_t = \sum_{s \le t} \alpha_s\, y_s</d-math> from <strong>eq (4.1)</strong> is the <strong>orthogonal projection</strong> <d-math>\Pi_{\mathcal{H}_t}(x_t)</d-math> of the latent state <d-math>x_t</d-math> onto the closed linear span <d-math>\mathcal{H}_t</d-math> of past observations <d-math>y_{1:t}</d-math>. The coefficients <d-math>\alpha_s</d-math> are then <em>defined by the orthogonality condition</em> - the residual must be uncorrelated with every past observation:</p> <d-math block="">\mathbb{E}\!\left[(x_t - \hat x_t)\, y_s^{\top}\right] \;=\; 0 \qquad \text{for all } s \leq t. \qquad\qquad (4.2)</d-math> <p>Solving this system gives the explicit form of each <d-math>\alpha_s</d-math>.</p> <p>The geometry the projection exposes - <strong>each new observation contributes only its unpredictable, orthogonal component</strong> (the <em>innovation</em>: the part of <d-math>y_t</d-math> not linearly predictable from $y_{1:t-1}$); whatever was already predictable from the past adds nothing new - is precisely what lets the optimum of <strong>eq (3.1)</strong> (equivalently, the conditional-mean summary of <strong>eq (3.2)</strong>) be computed <strong>recursively</strong>, one observation at a time, in constant memory, rather than as a batch re-solve over the full history. <strong>Conditional expectations in general do not compose this way</strong> - the projection structure is doing real work.</p> <p>That compute-friendly recursive form is what made the Kalman filter the workhorse of real-time navigation in the <strong>Apollo program</strong> (where on-board memory was measured in kilobytes), and the default tool for robotics, GPS, and control ever since. The same recursion also returns a covariance <d-math>P_t</d-math> tracking the second-moment uncertainty in the estimate.</p> <p>The orthogonal-projection geometry itself is unpacked further in <strong>§5</strong> - and there we will additionally derive the very same predict–update recursion using a different tool: <strong>Bayesian inference on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> viewed as a probabilistic graphical model</strong> (HMM-style message passing). For an ML audience that has already seen HMMs / belief propagation, that second route is often the more familiar one - and it lands on exactly the same equations.</p> </details> <blockquote> <p><strong>🟦 Relevance to modern linear RNN / SSM literature.</strong> Linear RNNs and linear SSMs are - by construction - linear functions of their input history. Thm 2 says <strong>we cannot theoretically do better than the Kalman recursion in an MSE sense within that class.</strong> The Kalman filter is the gold-standard linear MSE estimator for any linear state-space model. Beating it requires <strong>breaking linearity-in-input</strong> - via nonlinear smoothers, particle filters, attention, or data-dependent dynamics (selective SSMs like Mamba and KLA - exactly Part 2’s story).</p> </blockquote> <p><strong>Under Gaussianity: even stronger.</strong> Kalman’s own commentary on Thm 2 notes that Gaussianity broadens the result further. If the underlying process is in fact Gaussian (more generally: symmetric+unimodal posteriors - see the case-split inside the toggle in <strong>§3</strong>), <strong>Thm 1</strong> promotes the Kalman estimator from “best linear under MSE” to “best estimator overall, under <em>every</em> reasonable loss.” This isn’t irrelevant for what follows - there are KLA / SSM applications where the data are at least approximately Gaussian, and you get the stronger all-loss guarantee for free. <strong>And when Gaussianity doesn’t hold, Thm 2 alone - best linear MSE estimator - is already enough to make the Kalman recursion a very strong choice.</strong></p> <hr/> <h2 id="5-explaination-and-derivation-of-the-update-equations">5. Explaination and Derivation of the Update Equations</h2> <p>As a headsup only understanding what the update equations is a necessary primer for KLA in part 2, the full on derivations are not required and are discussed only for completeness.</p> <p>As discussed in <strong>§3</strong>, the inference ↔ optimisation duality on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> means the <em>same</em> Kalman recursion can be derived from several different toolboxes - each starting from a different side of the duality and landing on the same equations. We’ll call these <em>points of view</em> (POVs).</p> <p>Regardless of which POV one takes, every derivation of the KF threads through <strong>two canonical steps</strong>:</p> <ol> <li><strong>Prediction</strong> (a.k.a. <em>time update</em>) - given past observations $y_{1:t-1}$, what is my best guess for the system state at the next time step $t$, <em>before</em> seeing the new observation $y_t$?</li> <li><strong>Update</strong> (a.k.a. <em>observation update</em>) - now fold the fresh observation $y_t$ into that prediction, to get the best guess for the system state at time $t$ given <em>all</em> observations $y_{1:t}$ so far.</li> </ol> <p>The toggle below sketches <em>two</em> such POVs - one via optimisation, one via probabilistic inference on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> PGM - showing how each threads through these two steps and lands on the same recursion. The full derivations are beyond the scope of this primer and may be covered in separate posts; open the toggle only if you’d like intuition for the different tools one can use to derive the KF (and adapt them to your own SSM variants beyond the simple linear-Markovian case - switching models, hierarchical models, etc.). The <strong>Predict–Update cycle</strong> in <strong>§5.1</strong> below is what you actually need to follow Part 2.</p> <details> <summary><strong>(Optional) Sketch of the two KF derivations - via the inference / optimisation duality (§3) →</strong></summary> <p align="center"> <img src="/assets/img/kla_part1/two_views.png" alt="Composite figure: top half shows the system + Kalman filter frame; bottom half shows the same recursion drawn two ways - Bayesian PGM (with dashed back-arrows for inference) and Kalman's original orthogonal projection of the latent x_t onto the subspace spanned by past observations." width="900"/> </p> <p><strong>Figure 4.</strong> <em>Two POVs, identical recursion. <strong>Top</strong>: a recap of the system + observer frame. <strong>Bottom-left</strong> (POV 1): Bayesian posterior inference on the graphical model, with dashed back-arrows highlighting the direction of information flow during the update step. <strong>Bottom-right</strong> (POV 2): Kalman’s original 1960 derivation - the optimal linear estimate is the orthogonal projection of $x_t$ onto the subspace $\mathcal H_t$ spanned by past observations, with the residual error perpendicular to that subspace.</em></p> <p>Recall from <strong>§3</strong> that we established the <strong>(A) optimisation ↔ (B) inference</strong> duality: the optimal Kalman estimate can be defined <em>either</em> as the minimiser of an expected squared loss (<strong>eq 3.1</strong>) <em>or</em> as the conditional-mean summary of a posterior (<strong>eq 3.2</strong>). The two points of view below correspond to <strong>attacking the recursion through one side of that duality or the other</strong> - POV 1 from the inference side (B), POV 2 from the optimisation side (A) using the orthogonal-projection tool that <strong>Thm 2 (§4)</strong> handed us. They land on the <em>same</em> equations because, on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr>, the two sides coincide; which one feels more natural depends on your background.</p> <h4 id="pov-1--probabilistic-inference-on-the-lgssm-pgm">POV 1 — Probabilistic inference on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> PGM</h4> <p><em>(the (B) / inference side of the §3 duality)</em></p> <p>This is the standard-toolbox route, familiar to anyone who’s seen the <strong>HMM forward pass</strong> for discrete state-spaces - the linear-Gaussian case is its <strong>continuous-state analogue</strong>. The goal at each step is to compute the <strong>filtering posterior</strong></p> \[p(x_t \,\big|\, y_{1:t}) \tag{5.1}\] <p>on the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> viewed as a graphical model (latents $x_0 \to x_1 \to \cdots$ generate observations $y_t$; the filter <em>inverts</em> the generative arrow to infer the latent - forward solid arrows = generative, dashed back-arrows = inference). By <strong>Bayes’ rule</strong>, the posterior factorises into a likelihood times a prior, normalised by the marginal evidence:</p> <div style="border-left: 4px solid #4a90e2; padding: 8px 16px; margin: 16px 0; border-radius: 0 4px 4px 0;"> <strong>Update step — Bayes' Rule (eq 5.2)</strong> <d-math block="">p(x_t \mid y_{1:t}) \;=\; \frac{\overbrace{p(y_t \mid x_t)}^{\text{likelihood}} \;\; \overbrace{p(x_t \mid y_{1:t-1})}^{\text{prior}}}{\underbrace{p(y_t \mid y_{1:t-1})}_{\text{normaliser}}}</d-math> </div> <p>Under the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr>, all three factors are Gaussian, so the product (and quotient with the normaliser) stays Gaussian and this <strong>update step</strong> admits a <strong>closed-form</strong> solution.</p> <p>The prior $p(x_t \mid y_{1:t-1})$ in <strong>eq (5.2)</strong> is not free - it has to be <em>predicted</em> from the <strong>previous</strong> posterior by marginalising over $x_{t-1}$. The standard tool is the <strong>Chapman–Kolmogorov equation</strong> (the law of total probability applied to a Markov chain):</p> <div style="border-left: 4px solid #4a90e2; padding: 8px 16px; margin: 16px 0; border-radius: 0 4px 4px 0;"> <strong>Prediction step — Chapman–Kolmogorov (eq 5.3)</strong> <d-math block="">\underbrace{p(x_t \mid y_{1:t-1})}_{\text{prior at } t} \;=\; \int \underbrace{p(x_t \mid x_{t-1})}_{\text{transition model}} \;\; \underbrace{p(x_{t-1} \mid y_{1:t-1})}_{\text{previous posterior}} \, dx_{t-1}</d-math> </div> <p>Again, both factors inside the integral are Gaussian under the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr>, so this <strong>prediction step</strong> also collapses to a closed-form Gaussian.</p> <p>Together, <strong>eq (5.3)</strong> (Chapman–Kolmogorov prediction) and <strong>eq (5.2)</strong> (Bayes update) give the <strong>Predict–Update cycle</strong> that <strong>§5.1</strong> below unpacks concretely. The derivation reuses standard machinery from any inference / PGM course - message passing on the chain, conjugate Gaussian priors, a few Gaussian identities looked up in any textbook. Mechanical and cheap. The catch: it leans on the <em>Gaussianity</em> assumption; outside that, the recursion no longer closes in finite-dimensional sufficient statistics, and nonlinear / non-Gaussian extensions (EKF, UKF, particle filters) become necessary.</p> <h4 id="pov-2--orthogonal-projection-in-hilbert-space">POV 2 — Orthogonal projection in Hilbert space</h4> <p><em>(Kalman 1960; the (A) / optimisation side of the §3 duality)</em></p> <p><em>If you haven’t seen $L^2$ / Hilbert spaces before, POV 1 above already gives the same recursion via different machinery - feel free to skip POV 2 on first reading. The rigorous derivation is in Kalman’s original 1960 paper<d-cite key="kalman1960new"></d-cite>; what follows is the <strong>geometric intuition</strong>.</em></p> <p><strong>Setup.</strong> Treat every random vector as a point in the Hilbert space $L^2$ with inner product $\langle X, Y \rangle = \mathbb{E}[XY]$. Let $\mathcal H_t$ be the closed linear span of past observations $y_1, \ldots, y_t$. Kalman <em>defines</em> the estimate $\hat x_t$ as the orthogonal projection of the true latent onto $\mathcal H_t$:</p> \[\hat x_t \;=\; \Pi_{\mathcal H_t}(x_t). \tag{5.4}\] <p>Geometrically: drop a perpendicular from the point $x_t$ onto the subspace spanned by all observations seen so far. The residual $x_t - \hat x_t$ is then perpendicular to every $y_s$, $s \le t$ — that’s the <strong>orthogonality principle</strong> $\mathbb{E}[(x_t - \hat x_t)\, y_s^\top] = 0$.</p> <p><strong>Why this leads to a recursion - Gram–Schmidt on the fly.</strong> Naively, projecting onto a $t$-dimensional subspace would require inverting a $t \times t$ Gram matrix - quadratic memory, cubic compute, no good. Kalman’s trick: <strong>orthogonalise the observations one at a time as they arrive</strong>, so each step only has to handle one new direction.</p> <p>Walk through it concretely. At $t = 1$, $\mathcal H_1$ is a single direction $y_1$, and $\hat x_1$ is just the projection of $x_1$ onto that line. At $t = 2$, a new observation $y_2$ arrives. Decompose it orthogonally into the part already lying in $\mathcal H_1$ plus a new perpendicular component:</p> <d-math block="">y_2 \;=\; \underbrace{\hat y_{2 \mid 1}}_{\text{predictable from } y_1} \;+\; \underbrace{\tilde y_2}_{\text{innovation } \perp \mathcal H_1}</d-math> <p>where $\hat y_{2 \mid 1} = \mathbb{E}[y_2 \mid y_1] \in \mathcal H_1$ is the part of $y_2$ that was already in the old subspace, and $\tilde y_2 = y_2 - \hat y_{2 \mid 1}$ is the <strong>innovation</strong> — what’s genuinely new, perpendicular to $\mathcal H_1$. Crucially, ${y_1, \tilde y_2}$ is now an <strong>orthogonal basis</strong> for $\mathcal H_2$, and projecting onto an orthogonal basis is <em>trivial</em>: the projection of $x_2$ is just the sum of projections onto each basis vector — projection onto the old direction $y_1$ <em>plus</em> projection onto the new innovation direction $\tilde y_2$.</p> <p>The same structure holds at every step. The projection of $x_t$ onto $\mathcal H_t$ decomposes as the projection onto the old subspace $\mathcal H_{t-1}$ (the <strong>prior</strong>) plus a correction along the single new innovation direction:</p> <div style="border-left: 4px solid #4a90e2; padding: 8px 16px; margin: 16px 0; border-radius: 0 4px 4px 0;"> <strong>Recursive update — prior + innovation correction (eq 5.5)</strong> <d-math block="">\hat x_t \;=\; \underbrace{\hat x_{t \mid t-1}}_{\text{prior}} \;+\; \underbrace{K_t \, \tilde y_t}_{\text{correction along innovation}}</d-math> </div> <p>Here $\hat x_{t \mid t-1} = \Pi_{\mathcal H_{t-1}}(x_t)$ is the projection onto past observations — what we’d estimate from history alone, exactly POV 1’s prior $\mathbb{E}[x_t \mid y_{1:t-1}]$. The <strong>Kalman gain</strong> $K_t$ is the coefficient of the projection onto the new innovation direction $\tilde y_t$ — fixed by demanding the residual be perpendicular to $\tilde y_t$ (one-direction projection, cheap). <em>A few lines of linear algebra</em> turn $\hat x_{t \mid t-1}$ and $K_t$ into the closed-form Kalman recursion (see Kalman 1960<d-cite key="kalman1960new"></d-cite> for the rigorous derivation).</p> <p>The geometric pay-off: <em>every new observation contributes only the part of itself that’s orthogonal to everything seen before</em>. That’s what lets the recursion run in <strong>constant memory per step</strong> rather than re-solving over the full history.</p> <p><strong>Optimality.</strong> Theorem 2 of Kalman’s paper says this projection is the optimal estimator under squared loss within the linearity restriction, <em>without</em> any Gaussianity assumption; Theorem 1 (after Sherman 1958) lifts that to <em>every</em> reasonable loss whenever the posterior is symmetric and unimodal. This is the picture a signal-processing or statistics reader has, and it is what Kalman <em>actually wrote</em> in 1960, long before “Bayes nets” were standard. (See the case-split bridge in <strong>§3</strong> above for the precise theorem statements.)</p> <p>There are plenty of other routes too - exponential-family conjugacy, variational free energy, recursive least squares, you name it. Pick the comfort zone closest to your background; the recursion at the end is the same. (For the precise sense in which the result is “optimal” - and why our <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> gets a stronger guarantee than just MSE - see the case-split (Thm 1 vs Thm 1-a) in <strong>§3</strong> above.)</p> <p>For jointly Gaussian variables the two POVs are <em>formally identical</em></p> <ul> <li><strong>conditional expectation = orthogonal projection</strong>. Pick the picture that fits your audience and the rest of the math is bookkeeping.</li> </ul> </details> <blockquote> <p><strong>What you actually need to carry into Part 2.</strong> You will not rederive any of this. What matters is: at every step the KF emits a pair $(\mu_t, P_t)$ - posterior mean and covariance - and these obey a <em>linear</em> recursion in those quantities, equivalently in the natural parameters $(\Lambda_t, \eta_t)$. Some linear algebra turns the predict–update cycle into the closed-form Kalman equations; <em>which</em> derivation got you there (orthogonal projection, Bayes’ rule, exponential-family conjugacy) is a matter of taste. <strong>Part 2 holds the recursion structure fixed and reparameterises it for parallel computation - it does not rederive it.</strong></p> </blockquote> <h3 id="51-the-predict-update-cycle">5.1. The Predict-Update Cycle</h3> <p>To make what the filter does at each step concrete, here is what happens to its belief between two observations:</p> <div class="l-page" style="text-align:center;"> <img src="/assets/img/kla_part1/predict_update.png" alt="Static side-by-side diagram of the Kalman predict-update cycle. Left panel: the predict and update objectives stated as both (A) an optimization (argmin of expected squared error conditioned on past observations) and (B) an inference equation (Chapman-Kolmogorov for predict, Bayes' rule for update), with the closed-form LGSSM recursion equations below each. Right panel: three rows on a shared horizontal state axis, top to bottom - narrow green pill 'Posterior at t-1', wider orange pill 'Predict to Prior at t' (variance grew), narrow green pill 'Update to Posterior at t' shifted toward the red tick marking the observation y_t=1.0. Vertical arrow connects the predict step (no mean shift); slanted arrow connects the update step (mean shifts toward observation). Numerical mean and standard deviation values shown to the right of each pill." style="max-width:100%; height:auto;"/> </div> <p><strong>Figure 5.</strong> <em>The <strong>predict–update</strong> cycle, two views.</em></p> <p><strong>Left:</strong> the <strong>predict step</strong> can be cast as either solving an <em>optimisation</em> problem (argmin of expected squared error from past observations) or doing <em>inference</em>. For the <strong>NLP / HMM</strong> reader, that inference is just the <strong>marginalisation</strong> substep of the <strong>forward algorithm</strong> - known in continuous state-spaces as the <strong>Chapman–Kolmogorov</strong> equation. The <strong>update step</strong> is similarly either an <em>optimisation</em> (argmin after folding in the latest $y_t$) or <em>inference</em> - the <strong>conditioning</strong> substep of the forward algorithm, i.e. <strong>Bayes’ rule</strong> applied to $y_t$. On the <abbr title="Linear Gaussian State Space Model">LGSSM</abbr> both views collapse to the same <strong>closed-form recursion</strong> shown below each.</p> <p><strong>Right:</strong> <em>visual intuition</em> on how the belief evolves on a 1D state axis. <strong>The dot is the mean (first moment); the shaded region around it is the variance (second moment)</strong> — only these two moments are committed, no Gaussianity required (matching Thm 2 of §4). <b style="color:#2E7D32">posterior at $\textcolor{#2E7D32}{t-1}$</b> → <strong>predict</strong> widens it to the <b style="color:#C66A00">prior at $\textcolor{#C66A00}{t}$</b> (variance grows by additive process noise $Q$) → <strong>update</strong> folds in the <b style="color:#D32F2F">observation $\textcolor{#D32F2F}{y_t}$</b>, giving a tighter <b style="color:#2E7D32">posterior at $\textcolor{#2E7D32}{t}$</b>. <strong>Predict always <em>widens</em> uncertainty; update always <em>tightens</em> it</strong> — or, in the worst case (missing observation $\equiv$ infinite observation variance / zero precision), leaves it equal. <strong>Update never makes things worse.</strong>*</p> <p>For reference - the closed-form <strong><abbr title="Linear Gaussian State Space Model">LGSSM</abbr> recursion</strong> shown inside Figure 5, written out for copy-paste convenience.</p> <p><strong>Predict step</strong> - propagate the previous posterior through the dynamics:</p> \[\mu_t^- \;=\; A\, \mu_{t-1}, \qquad P_t^- \;=\; A\, P_{t-1}\, A^{\!\top} + \Sigma^{\mathrm{proc}} \tag{5.3}\] <p><strong>Update step</strong> - fold in the new observation $y_t$ via the <strong>Kalman gain</strong> $K_t$:</p> \[K_t \;=\; P_t^-\, C^{\!\top} \bigl(C\, P_t^-\, C^{\!\top} + \Sigma^{\mathrm{obs}}\bigr)^{-1} \tag{5.4}\] \[\mu_t \;=\; \mu_t^- + K_t\,(y_t - C\, \mu_t^-), \qquad P_t \;=\; (I - K_t C)\, P_t^- \tag{5.5}\] <hr/> <h2 id="6-a-classical-kalman-filter-in-action">6. A Classical Kalman Filter in Action</h2> <p>Enough abstraction. Let’s see one work.</p> <blockquote> <p><strong>🎬 The setup.</strong> James Bond is on vacation, having a private call in a closed 1-D corridor. His security agency wants to track his movements for safety <strong>without compromising privacy</strong> - they only have an inexpensive, noisy position sensor on his phone. The agency uses a Kalman filter to fuse the sequence of <em>sparse, noisy</em> sensor readings and estimate / predict in real time Bond’s <strong>position</strong> <em>and</em> <strong>velocity</strong>.</p> </blockquote> <div class="l-body-outset" style="text-align:center;"> <img src="/assets/img/kla_part1/kf_pgm_trajectory.gif" alt="Animated Kalman filter on the Bond-tracking scenario. Four panels: top - graphical model with sparse observations; predict / update equation cells flashing during their respective phases; position vs time with truth, noisy obs, KF mean, and ±2σ band; velocity vs time (latent, no observations); spatial 1D corridor view of Bond and the KF ghost estimate." style="max-width:100%; height:auto;"/> </div> <p><strong>Figure 6.</strong> <em>The full pipeline in motion. Watch the orange ghost overshoot during predict steps, the green posterior snap back at every ping, and the velocity panel quietly track the truth even though it never receives a single direct observation.</em></p> <h3 id="61-what-to-watch-in-the-animation">6.1. What to Watch in the Animation</h3> <p>A quick tour of the four panels, top to bottom:</p> <p><strong>Top - graphical model + predict/update.</strong> Kalman filtering viewed as <strong>posterior inference in an SSM</strong>. The <span style="color:#e07a3c;">predict</span> step rolls the latent $x$ forward through the causal dynamics $(A, \Sigma^{\mathrm{proc}})$ to give the prior $p(x_t \mid y_{1:t-1})$; the <span style="color:#2e8b57;">update</span> step performs a <strong>Bayesian inversion</strong> - the green dashed back-arrow $y_t \to x_t$ in the PGM - to fold in the new noisy observation and give the posterior $p(x_t \mid y_{1:t})$. When no ping arrives at a step, we simply carry the prior forward.</p> <p><strong>Second row - position over time.</strong> True position $p_t$ in <span style="color:#1f4e9e;">blue</span>; noisy position sensor data ($y_t$) as <span style="color:#d83a3a;">red dots</span>; filter mean $\hat{\mu}_p$ in <span style="color:#e07a3c;">orange</span>, with the $\pm 2\sigma$ uncertainty band shaded around it.</p> <p><strong>Third row - velocity over time.</strong> Same colour scheme for the latent velocity, except <strong>there are no <span style="color:#d83a3a;">red dots (🔴)</span></strong> - no velocity sensor exists. The filter must infer velocity purely from the <em>pattern</em> of incoming position sensor data.</p> <p><strong>Bottom - 1-D corridor (spatial view).</strong> Bond (<span style="color:#1f4e9e;">solid blue 🧍</span>) paces the corridor in real time; the dashed ghost is the filter’s belief - <span style="color:#e07a3c;">orange (🧍)</span> during predict (the prior), <span style="color:#2e8b57;">green (🧍)</span> during update (the posterior). The footprint underfoot is the same $\pm 2\sigma$ band as in the panels above. Each <span style="color:#d83a3a;"><strong>ping (🛜)</strong></span> appears as red wifi arcs above the corridor and a red triangle on the floor at the noisy reading.</p> <hr/> <p>Two things to notice - and to expect in most Kalman applications:</p> <p><strong>1. Between <span style="color:#d83a3a;">pings (🛜)</span>, the filter coasts on its <span style="color:#e07a3c;">predict step (🧍)</span> and tends to drift from the truth.</strong> With no new evidence, the prior can only roll forward through the assumed dynamics; the estimate becomes inaccurate and the uncertainty band grows under the process noise $\Sigma^{\mathrm{proc}}$. The next ping then grounds the estimate, <span style="color:#2e8b57;">snapping it back toward truth</span> and shrinking the band.</p> <p><strong>2. Hidden quantities can be recovered reliably, even when direct sensing is impossible.</strong> Velocity here is a tame example - in practice the same machinery recovers things like <strong>neuronal activity</strong> in the brain from indirect biosignals, or <strong>atmospheric state</strong> from sparse weather stations. The Kalman filter pieces them together from the <em>pattern</em> of related observations, in real time and at constant compute per step.</p> <h3 id="62-designing-the-generative-model">6.2. Designing the Generative Model</h3> <p>Now let’s pop the hood. In a classical application of Kalman filtering, the modelling effort is front-loaded: you spend most of your time <strong>designing the generative model</strong> - the transition matrix $A$, the observation matrix $H$, and the noise covariances $\Sigma^{\mathrm{proc}}$ and $\Sigma^{\mathrm{obs}}$ - and only then turn the predict-update recursion of <strong>§5</strong> loose on the incoming data. Here are the four design choices that produce the Bond scenario, with the trade-offs and intuition behind each.</p> <p><strong>Step 1 - pick the latent state.</strong> We track</p> \[x_t \;=\; \begin{pmatrix} p_t \\ v_t \end{pmatrix} \in \mathbb{R}^2, \tag{6.1}\] <p>position <em>and</em> velocity, even though no sensor ever reads velocity. Why include it? Position alone tells you where Bond <em>is</em>, not where he is <em>going</em> - without velocity, the filter has no way to extrapolate between pings. The latent state is exactly the set of quantities you’d need to <em>roll the world forward by one step</em>.</p> <p><strong>Step 2 - pick the transition matrix $A$.</strong> The agency picks the simplest reasonable dynamics - <strong>constant velocity</strong>:</p> \[\begin{pmatrix} p_{t+1} \\ v_{t+1} \end{pmatrix} \;=\; \underbrace{\begin{pmatrix} 1 &amp; \Delta t \\ 0 &amp; 1 \end{pmatrix}}_{A} \begin{pmatrix} p_{t} \\ v_{t} \end{pmatrix} \;+\; \mathbf{w}_t, \qquad \mathbf{w}_t \sim \mathcal{N}\!\bigl(0,\,\Sigma^{\mathrm{proc}}\bigr). \tag{6.2}\] <p>In words: <em>“position drifts forward by velocity $\times \Delta t$; velocity stays the same.”</em> This model is <strong>deliberately wrong</strong> - Bond’s true motion is a sinusoid, not a straight line. That’s the universal practical lesson: in any real application your dynamics is <em>always</em> a simplification, and the role of $\Sigma^{\mathrm{proc}}$ is to tell the filter <em>how wrong</em>.</p> <p><strong>Step 3 - pick the observation matrix $C$.</strong> The cheap phone sensor only reads position, so</p> \[y_t \;=\; C\, x_t + v_t, \qquad C = (1\;\;0), \qquad v_t \sim \mathcal{N}\!\bigl(0,\,\Sigma^{\mathrm{obs}}\bigr). \tag{6.3}\] <p>$C$ literally selects “the position component of $x_t$”. Richer sensors (e.g. position <em>and</em> heading) would just give $C$ more rows.</p> <p><strong>Step 4 - pick the noise covariances.</strong> $\Sigma^{\mathrm{proc}}$ and $\Sigma^{\mathrm{obs}}$ are the filter’s two <strong>tuning knobs</strong> - they encode <em>trust</em> rather than measure anything physical:</p> \[\Sigma^{\mathrm{proc}} \;=\; \begin{pmatrix} 10^{-3} &amp; 0 \\ 0 &amp; 0.05 \end{pmatrix}, \qquad \Sigma^{\mathrm{obs}} \;=\; (0.20)^2. \tag{6.4}\] <p>The small $(1,1)$ entry of $\Sigma^{\mathrm{proc}}$ says <em>“position barely drifts on its own”</em> - it’s mostly determined by velocity. The larger $(2,2)$ entry says <em>“I expect velocity to wander by $\approx \pm 0.22$ per step”</em> - wide enough to absorb the unmodelled acceleration of the sinusoidal truth. The $(0.20)^2$ on the sensor side says <em>“the phone sensor is accurate to about $\pm 20$ cm.”</em> What ultimately matters for the Kalman gain $K_t$ is the <strong>ratio</strong> $\Sigma^{\mathrm{proc}} / \Sigma^{\mathrm{obs}}$ - not the absolute scales.</p> <p>With $A, H, \Sigma^{\mathrm{proc}}, \Sigma^{\mathrm{obs}}$ in hand, the rest is mechanical: feed the incoming pings $y_2, y_4, \dots$ from the noisy position sensor into the predict-update recursion of <strong>§5</strong>, and read off the posterior mean $\mu_t$ and covariance $P_t$ at every step. The remarkable thing is that even though <strong>velocity is never directly observed</strong>, the recursion produces a perfectly reasonable real-time estimate of it - and at <strong>constant compute per step</strong>, because the running posterior $(\mu_t, P_t)$ is a sufficient summary of everything the filter has seen so far.</p> <blockquote> <p><strong>💡 What changes in KLA (Part 2).</strong> KLA reuses the recursion of §5 but departs from the classical setup above in two structural ways.</p> <ol> <li><strong>Non-linear feature lift.</strong> The “noisy observations” $y$ - for KLA, input tokens - are first pushed through a <strong>deep encoder</strong> before they enter the recursion. The Kalman update still runs in a linear-Gaussian latent space, but that latent now lives in the encoder’s feature space rather than the raw observation space.</li> <li><strong>All four quantities are <em>learned</em>, not hand-designed.</strong> $A, H, \Sigma^{\mathrm{proc}}, \Sigma^{\mathrm{obs}}$ become differentiable parameters fit by gradient descent on a downstream task - no constant-velocity assumption, no hand-tuned noise scales, no manually-picked $C = (1\;\;0)$.</li> </ol> <p>The recursion itself is unchanged; what changes is <strong>who picks the matrices</strong>.</p> </blockquote> <p>If you’d like to play with the simulation - change the noise covariances, the obs rate, the truth itself - see the companion Jupyter notebook (<code class="language-plaintext highlighter-rouge">kf_tutorial.ipynb</code> in the <a href="https://github.com/vaisakh-shaj/">GitHub repo</a>), which builds the filter step by step with running plots.</p> <hr/> <h2 id="7-going-further">7. Going Further</h2> <p>The actual derivation of the predict–update equations is beyond the scope of this primer; both views (Bayesian and orthogonal-projection) are spelled out in detail in the references below.</p> <ul> <li><strong>Shaj, V. et al. (2026).</strong> <em><a href="https://arxiv.org/abs/2602.10743">Kalman Linear Attention: Parallel Bayesian Filtering for Efficient Language Modelling and State Tracking</a>.</em><d-cite key="shaj2026kalman"></d-cite> ICML 2026. The KLA paper this primer series is built around - reframes linear attention as a learnable Kalman recursion with closed-form predict-update steps and linear-time parallel training.</li> <li><strong>Kalman, R. E. (1960).</strong> <em><a href="https://www.unitedthc.com/DSP/Kalman1960.pdf">A New Approach to Linear Filtering and Prediction Problems</a>.</em><d-cite key="kalman1960new"></d-cite> The original paper - surprisingly readable, and worth reading for the geometric (Hilbert-space) derivation that modern ML treatments often skip.</li> <li><strong>Bishop, G. &amp; Welch, G. (2001).</strong> <em><a href="https://www.cs.unc.edu/~welch/media/pdf/kalman_intro.pdf">An Introduction to the Kalman Filter</a>.</em><d-cite key="bishop2001introduction"></d-cite> The classic SIGGRAPH course note - a compact, practitioner-oriented walkthrough that complements Kalman’s original paper.</li> <li><strong>Bzarg.</strong> <em><a href="https://www.bzarg.com/p/how-a-kalman-filter-works-in-pictures/">How a Kalman filter works, in pictures</a>.</em> The clearest visual intuition I know of for the update step (overlapping Gaussians).</li> <li><strong>Eric Xing.</strong> <em><a href="https://scs.hosted.panopto.com/Panopto/Pages/Viewer.aspx?id=77665f85-3445-4146-b0c6-a9d00129cf56">Sequential Models (lecture)</a>.</em> A graduate-level lecture connecting HMMs, Kalman filters, and the broader family of sequential latent-variable models - useful for placing the KF inside the wider PGM landscape.</li> </ul> <p>In <strong>Part 2</strong>, we’ll see how the predict–update recursion can be reframed as a <em>linear-attention layer</em>, and how that leads naturally to <strong>Kalman Linear Attention (KLA)</strong> - our drop-in probabilistic primitive for sequence modelling that retains all the parallel-training goodness of modern transformers but adds principled uncertainty estimates and richer state-tracking expressivity.</p> <hr/> ]]></content><author><name>Vaisakh</name></author><summary type="html"><![CDATA[An intuitive introduction to Kalman filters - from state observers to predict-update recursions - and why they matter for modern sequence models]]></summary></entry><entry><title type="html">Control As Inference In PGMs (Part 1) - Why is it Interesting?</title><link href="https://vaisakh-shaj.github.io/blog/2022/Control_1/" rel="alternate" type="text/html" title="Control As Inference In PGMs (Part 1) - Why is it Interesting?"/><published>2022-06-18T00:00:00+00:00</published><updated>2022-06-18T00:00:00+00:00</updated><id>https://vaisakh-shaj.github.io/blog/2022/Control_1</id><content type="html" xml:base="https://vaisakh-shaj.github.io/blog/2022/Control_1/"><![CDATA[<h2 id="motivation-for-this-blog">Motivation For This Blog</h2> <p>Probabilistic Graphical Models (PGMs) are powerful tools for representing relationships between random variables using graphs (directed or undirected). Once we come up with a representation of the stochastic phenomenon we wish to model, PGMs provide a consistent and flexible framework to devise principled objectives, set up models that reflect the causal structure in the world, and allow a common set of inference methods to be deployed against a broad range of problem domains.</p> <p>This blog will try to summarize how Reinforcement Learning can be brought under the PGM framework which allows us to transfer policy search from an optimization point of view to an inference point of view. Also, we will see how this framework allows us to recover “soft” versions of Bellman backup equations from classical RL.</p> <h2 id="premise-">Premise :</h2> <p>Human or animal behaviour is not often perfectly optimal but approximately optimal. For example, an animal/human being whose only goal is to move from the start position to the goal position as shown in figure 1 can choose any choose either perfectly optimal/hard optimal (green) trajectory or suboptimal (blue) trajectory but typically would avoid the red trajectories which specify bad behaviour.</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220616-114919_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220616-114919_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220616-114919_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220616-114919_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <div class="caption"> Figure 1: Stochastic and Suboptimal Human/Agent Behaviour </div> <p>We need a probabilistic framework for this <strong>stochastic</strong> phenomenon of <strong>goal-directed behaviour.</strong> The framework, in addition to giving a higher probability to perfectly optimal behaviour, should also give a non-zero probability to suboptimal behaviour. Similarly, a near-zero probability should be assigned to bad behaviour that misses reaching the goal.</p> <p>In machine learning whenever we have a stochastic phenomenon, we usually come up with a probabilistic graphical model (PGM) based on the observed stochastic phenomenon, such that the samples from this model will look like the observed stochastic phenomenon.</p> <p>Thus we need a PGM that models optimal decision-making. Let’s first model a PGM that models the relationship between states, actions and next states as in figure 2.</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220616-114112_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220616-114112_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220616-114112_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220616-114112_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <div class="caption"> Figure 2: PGM for physically consistent dynamics </div> <p>This PGM in figure 2, commonly known as a state space model (SSM), can represent physically consistent trajectories but for control/decision making we need a notion of cost/reward/optimality. Thus we modify the PGM to introduce additional optimality variables into the PGM, which is defined as $p(O_t=1 \mid s_t,a_t) = exp(r(s_t,a_t))$.</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220616-114134_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220616-114134_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220616-114134_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220616-114134_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <div class="caption"> Figure 3: PGM for optimal decision making </div> <p>Thus $O_t$ is defined as a binary random variable which indicates if the behaviour at time t was optimal or not. The reason why we define this as the exponential of the reward function is to make a convenient distinction between optimal (best way to reach a goal), sub-optimal (reaches the goal but not optimally) and bad behaviour (fails to reach the goal). This will become more apparent in the next section.</p> <h2 id="motivation-for-why-control-as-inference-is-an-interesting-paradigm">Motivation For Why Control As Inference Is An Interesting Paradigm</h2> <ol> <li><strong>Convenient Way For Representing and Sampling Optimal and Suboptimal Behaviour</strong></li> </ol> <p>Let’s derive a mathematical expression for the probability of a trajectory (state action sequence) given the observed optimality variables. We will see that based on the PGM we can derive an expression where optimal/sub-optimal trajectories can be conveniently represented.</p> \[\begin{aligned}p\left(\tau \mid\mathcal{O}_{1: T}\right) &amp; = \frac{p\left(\tau, \mathcal{O}_{1: T}\right)}{p\left( \mathcal{O}_{1: T}\right)} \\ &amp; \propto p\left(\tau, \mathcal{O}_{1: T}\right)\\ &amp; = p\left(s_{1}\right) \prod_{t=1}^{T} p\left(a_{t} \mid s_{t}\right) p\left(s_{t+1} \mid s_{t}, a_{t}\right) p\left(\mathcal{O}_{t} \mid s_{t}, a_{t}\right) \\ &amp;=p\left(s_{1}\right) \prod_{t=1}^{T} p\left(s_{t+1} \mid s_{t}, a_{t}\right)p\left(a_{t} \mid s_{t}\right) \exp \left(r\left(s_{t}, a_{t}\right) \right) \\ &amp;=\left[\underbrace{p\left(s_{1}\right) \prod_{t=1}^{T} p\left(s_{t+1} \mid s_{t}, a_{t}\right)p\left(a_{t} \mid s_{t}\right)}_\text{physical consistent dynamics with action prior}\right] \underbrace{\exp \left(\sum_{t=1}^{T} r\left(s_{t}, a_{t}\right) \right)}_\text{exponential of sum of rewards}\\ &amp;=\left[\underbrace{p\left(s_{1}\right) \prod_{t=1}^{T} p\left(s_{t+1} \mid s_{t}, a_{t}\right)}_\text{physical consistent dynamics }\right] \underbrace{\exp \left(\sum_{t=1}^{T} r\left(s_{t}, a_{t}\right) + p\left(a_{t} \mid s_{t}\right) \right)}_\text{exponential of sum of modified rewards} \end{aligned}\] <p>As we can see, those trajectories which are physically consistent and optimal (in terms of long-term rewards) have a higher probability mass. Additionally, a suboptimal trajectory with a slightly lesser reward can also be modelled/sampled using this graphical model framework which is important in several settings including inverse reinforcement learning.</p> <p>Note: One could ignore the action prior or assume a uniform action prior to further simplify the equations.</p> <p><strong>2. Can use established inference schemes to answer several queries including:</strong></p> <ul> <li> <p><strong>Policy Search:</strong> Given a reward, infer the optimal policy by calculating $p(a_t \mid s_t, O_{t:T})$. Instead of solving the optimization problem, we now can solve the inference problem. This will be discussed in detail in part 2 of this blog. Further, an approximate inference scheme based on variational/optimization-based formulation is discussed in part 3 of this blog.</p> </li> <li> <p><strong>Inverse Reinforcement Learning:</strong> Given a collection of optimal trajectories, infer the reward and action priors, which is basically an inverse RL question.</p> \[\begin{aligned} p\left(\tau, \mathcal{O}_{1: T}, \theta, \phi\right) &amp; \propto\left[p\left(s_{1}\right) \prod_{t=1}^{T} p\left(s_{t+1} \mid s_{t}, a_{t}\right)\right] \times \\ &amp;\quad\quad\quad\quad\quad\quad\exp \left(\sum_{t=1}^{T} r_{\phi}\left(s_{t}, a_{t}\right)+\log p_{\theta}\left(a_{t} \mid s_{t}\right)\right) \\&amp;=\left[p\left(s_{1}\right) \prod_{t=1}^{T} p\left(s_{t+1} \mid s_{t}, a_{t}\right)\right]\times \\ &amp;\quad\quad\quad\quad\quad\quad\operatorname{exp}\left(\sum_{t=1}^{T} \phi^{T} f_{r}\left(s_{t}, a_{t}\right)+\log \theta^{T} f_{p}\left(a_{t} \mid s_{t}\right)\right) \end{aligned}\] </li> </ul> <p><strong>3. Allows to model stochastic behaviour which has several advantages</strong></p> <ul> <li> <p><strong>Transfer Learning</strong>: If we can model multiple ways to solve a particular task, this turns to be relevant for transfer learning in a new setting where the task has to be solved in a slightly different manner.</p> </li> <li> <p><strong>Better Exploration Strategies</strong>: We will see that the maximum extropy objective that we derive in the 3rd part of this blog series on Policy Search as Variational Inference will provide a natural exploration strategy based on entropy maximization.</p> </li> </ul> <p>The blog is based on the following reference, <a href="https://arxiv.org/abs/1805.00909">Levine, 2018</a>.</p>]]></content><author><name>Vaisakh</name></author><summary type="html"><![CDATA[Introduction and motivation to control as inference paradigm]]></summary></entry><entry><title type="html">Control As Inference In PGMs (Part 2) - Policy Search Via Exact Inference</title><link href="https://vaisakh-shaj.github.io/blog/2022/Control_2/" rel="alternate" type="text/html" title="Control As Inference In PGMs (Part 2) - Policy Search Via Exact Inference"/><published>2022-06-18T00:00:00+00:00</published><updated>2022-06-18T00:00:00+00:00</updated><id>https://vaisakh-shaj.github.io/blog/2022/Control_2</id><content type="html" xml:base="https://vaisakh-shaj.github.io/blog/2022/Control_2/"><![CDATA[<p>In the 1st part of the blog series on control as inference, we discussed why this paradigm is interesting. In the second part of the blog, we will discuss how we can treat policy search as exact inference in this graphical model via variable elimination.</p> <p>We will see that the subroutines in the policy search procedure in this graphical model result in “soft” variations of bellman update equations, where the hard max in operation is replaced by a softmax.</p> <h2 id="log-sum-exp-trick">Log Sum Exp Trick</h2> <p>A useful “trick” to remember before we jump into control as inference procedure is “Log Sum Exp” trick. The LogSumExp (LSE) (also called RealSoftMax or multivariable softplus) function is defined as the logarithm of the sum of the exponentials of the arguments:</p> \[\operatorname{LSE}\left(x_{1}, \ldots, x_{n}\right)=\log \left(\exp \left(x_{1}\right)+\cdots+\exp \left(x_{n}\right)\right)\] <p>The LSE function is a smooth maximum – a smooth approximation to the maximum function, mainly used by machine learning algorithms. In the following inference procedure, we will replace LSE with max/softmax to derive a soft version of classical RL.</p> <h2 id="exact-inference-by-recursive-computation-of-backward-messages">Exact Inference By Recursive Computation Of Backward Messages</h2> <p>At any time t policy search involves computing the posterior over the action $a_t$, given state $s_t$ and the optimality variables $O_{t:T}$, i.e.</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220608-105322_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220608-105322_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220608-105322_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220608-105322_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>Thus policy search involves computing two backward messages \(\color{orange} \beta_{t}\left(\mathbf{s}_{t}\right)\) and \(\color{purple} \beta_{t}\left(\mathbf{s}_{t},\mathbf{a}_{t}\right)\). This is computed via backward messages similar to HMM or Kalman Smoothers as follows:</p> <p>At the last time step T:</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220608-110200_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220608-110200_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220608-110200_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220608-110200_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p><strong>Note on Action Prior</strong>: Here $p(a_t \mid s_t)$ is the action prior. Note that it is not conditioned on $O_{1:T}$ in any way, i.e. it does not denote the probability of an optimal action, but simply the prior probability of actions. The PGM for RL as inference doesn’t actually contain this factor, and we can assume that $ p\left(a_t \mid s_t \right)= \frac{1}{ \mid \mathcal{A} \mid} $ for simplicity. That is, it is a constant corresponding to a uniform distribution over the set of actions.</p> <p><strong>Thought Exercise</strong>:</p> <p><a href="https://arxiv.org/abs/1805.00909">Levine 2018</a><d-cite key="levine2018reinforcement"></d-cite> assumes a uniform action prior and argues that this assumption does not introduce any loss of generality. One could show that any non-uniform action prior $p(a_t \mid s_t)$ can be incorporated into $p(O_t \mid s_t,a_t):=exp(r_1(s_t,a_t))$ via a modified reward function $r_1(s_t,a_t)$.</p> <p>At any time step t</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220611-181313_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220611-181313_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220611-181313_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220611-181313_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <h2 id="intuition--relationship-to-classical-rl">Intuition / Relationship To Classical RL</h2> <p>In order to get an intuitive meaning of these messages, we do some algebraic manipulation in the log space to get a form similar to bellman backup. The messages in log space are as follows:</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220611-133851_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220611-133851_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220611-133851_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220611-133851_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <div class="caption"> Equation 1: Messages in log space </div> <p>One can show that if we replace the $\log \beta(s_t,a_t)$ with Q function and $\log \beta(s_t)$ with the value function we can recover an intuitive relationship resembling bellman backup operator in the deterministic case and an optimistic bellman backup in the stochastic case. Let,</p> \[\begin{aligned} \color{purple} Q\left(\mathbf{s}_{t}, \mathbf{a}_{t} \right) &amp;= \log \beta_{t}\left(\mathbf{s}_{t}, \mathbf{a}_{t} \right) \\ \color{orange}V\left(\mathbf{s}_{t}\right) &amp;= \log \beta_{t}\left(\mathbf{s}_{t} \right) \end{aligned}\] <div class="caption"> Equation 2: Relationship between backward messages and Q/Value functions in classical RL. </div> <p>Using Equations 1 and 2, now the messages in the log space look as follows:</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220611-181528_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220611-181528_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220611-181528_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220611-181528_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <h3 id="deterministic-case-regular-bellman-backup">Deterministic Case (Regular Bellman Backup)</h3> <p>In the deterministic case since we only have one possibility for transition dynamics, we obtain a backup equation similar to the regular Bellman backup equation.</p> \[\color{purple}Q\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)=\color{black}r\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)+\color{orange}V\left(\mathbf{s}_{t+1}\right)\] <h3 id="stochastic-case-optimistic-backup">Stochastic Case (Optimistic Backup)</h3> <p>In the stochastic case we obtain a backup equation that is optimistic as shown below:</p> \[\color{purple}Q\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)=\color{black}r\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)+\log E_{\mathbf{s}_{t+1} \sim p\left(\mathbf{s}_{t+1} \mid \mathbf{s}_{t}, \mathbf{a}_{t}\right)}\left[\exp \left(\color{orange}V\left(\mathbf{s}_{t+1}\color{black}\right)\right)\right]\] <p>The optimistic update occurs because it is largely determined by the max of the next state value, which creates risk-seeking behaviour.</p> <p>This issue will be mitigated by variational inference discussed in the next part of this blog series.</p>]]></content><author><name>Vaisakh</name></author><summary type="html"><![CDATA[Viewing policy search as an exact inference procedure in a graphical model]]></summary></entry><entry><title type="html">Control As Inference In PGMs (Part 3) - Policy Search Via Variational Inference</title><link href="https://vaisakh-shaj.github.io/blog/2022/Control_3/" rel="alternate" type="text/html" title="Control As Inference In PGMs (Part 3) - Policy Search Via Variational Inference"/><published>2022-06-18T00:00:00+00:00</published><updated>2022-06-18T00:00:00+00:00</updated><id>https://vaisakh-shaj.github.io/blog/2022/Control_3</id><content type="html" xml:base="https://vaisakh-shaj.github.io/blog/2022/Control_3/"><![CDATA[<p>In the 3rd part of this blog, we will discuss another paradigm, where policy search is reframed as an optimization problem via approximate inference<d-cite key="levine2018reinforcement"></d-cite>. We will see that this formulation allows us to make a distinction between controllable and non-controllable blocks in the graphical model and thus avoid the optimistic Bellman Update we obtained in part 2 of this blog series. In addition, we arrive at a <strong>max entropy RL objective</strong> which is critical for exploration and learning diverse skills.</p> <h2 id="which-objective-does-the-inference-procedure-in-exact-inference-in-part-2-solve">Which objective does the inference procedure in <a href="https://vaisakh-shaj.github.io/blog/2022/Control_2/">Exact Inference in Part 2</a> solve?</h2> <p>The inference procedure discussed in part 2 of this blog series solve the following objective: $\color{red} \text{minimize} \quad D_{\mathrm{KL}}(\color{green} q_\phi(\tau)\color{red} | \color{orange} p(\tau)\color{red}) = \color{red} \text{minimize} \quad D_{\mathrm{KL}}(\color{green} q_\phi(s_{1:T},a_{1:T}) \color{red} | \color{orange} p(s_{1:T},a_{1:T},O_{1:T})\color{red})$</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220609-103258_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220609-103258_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220609-103258_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220609-103258_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>Here the join distribution of optimal trajecories is given as follows:</p> \[\color{orange} p(\tau) = \color{black}\left[p\left(\mathbf{s}_{1}\right) \prod_{t=1}^{T} p\left(\mathbf{s}_{t+1} \mid \mathbf{s}_{t}, \mathbf{a}_{t}\right)\right] \exp \left(\sum_{t=1}^{T} r\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)\right)\] <h2 id="which-variational-distribution-to-choose-">Which variational distribution to choose ??</h2> <p>Looking at the graphical model for the variational distribution, the joint distribution for \(q(\tau)\) should be \(q(\tau)=q\left(\mathbf{s}_{1}\right) \prod_{t=1}^{T} q\left(\mathbf{s}_{t+1} \mid \mathbf{s}_{t}, \mathbf{a}_{t}\right) \pi\left(\mathbf{a}_{t} \mid \mathbf{s}_{t}\right)\).</p> <p>Here unlike in the exact inference case, we make an explicit assumption on what part of the graphical model is controllable by agent and what is not. It is reasonable to assume that the transition dynamics is not controllable by the agent and hence we fix \(q\left(\mathbf{s}_{1}\right)=p\left(\mathbf{s}_{1}\right) \text { and } q\left(\mathbf{s}_{t+1} \mid \mathbf{s}_{t}, \mathbf{a}_{t}\right)=p\left(\mathbf{s}_{t+1} \mid \mathbf{s}_{t}, \mathbf{a}_{t}\right)\).</p> <h2 id="derivation-of-max-entropy-rl-objective">Derivation Of Max Entropy RL Objective</h2> <p>In can be shown that minimizing this optimization objective results in max entorpy reinforcement learning objective as derived below:</p> \[\begin{aligned} &amp;\min KL \left( \color{green}q(\tau) \| \color{orange}p(\tau)\right) =\max -E_{\color{green}q(\tau)} \log \frac{\color{green}q(\tau)}{\color{orange}p(\tau)} \\ &amp;=\max E_{\color{green}q(\tau)}-\color{green} \log p\left(s_{0}\right)-\sum_{t=1}^{T} \log p(s_{t+1}\mid s_{t},a_{t})-\sum_{t=1}^{T} \log \pi_{\phi}\left(a_{t} \mid s_{t}\right) \\ &amp; \quad\quad\quad\color{orange}+ \log p\left(s_{0}\right) + \sum_{t=1}^{T} \log p\left(s_{t+1} \mid s_{t},a_{t}\right)+\sum_{t=1}^{T} \log p\left(O_{t} \mid s_{t}, a_{t}\right) \\ &amp;=\max \underset{q(\tau)}{E}\left[\color{orange} \sum_{t=1}^{T} \log (\exp (r(s_{t}, a_{t}))\color{green}-\sum_{t=1}^{T} \log \pi\left(a_{t} \mid s_{t})\right.\right]. \\ &amp;=\max \underbrace{\underset{q(\tau)}{E}\left[\sum_{t=1}^{T} r\left(s_{t}, a_{t}\right)\right]}_{\text{reward maximization}}+\underbrace{\sum_{t=1}^{T} H(\pi\left(a_{t} \mid s_{t})\right)}_{\text{conditional entropy maximization}}\end{aligned}\] <h2 id="deriving-soft-bellman-equations">Deriving Soft Bellman Equations</h2> <p>We now look at message passing (backward messages) from an optimization point of view. To calculate the backward messages we start from the last time step.</p> <p>At the last time step T</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220610-110228_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220610-110228_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220610-110228_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220610-110228_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>However, note that here we consider a general scenario where the reward can take any real value, $-\infty &lt; r(s,a) &lt; \infty$ , as opposed to the earlier restriction to be negative or zero. Thus we need to normalize $\exp(\log(r(s_T,a_T)))$, using the normalizing constant $V(s_T)=\int_{\mathbb{A}}\exp(r(s_T,a_T)) da_T$.</p> <p>Thus we do a little bit more algebraic manipulation to include this normalization constant as follows:</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220610-114252_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220610-114252_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220610-114252_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220610-114252_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>The optimal policy that minimizes this objective is given as :</p> \[\begin{aligned} \color{green}\pi^*\left(\mathbf{a}_{T} \mid \mathbf{s}_{T}\right)&amp;=\exp \left(r\left(\mathbf{s}_{T}, \mathbf{a}_{T}\right)-V\left(\mathbf{s}_{T}\right)\right)\\ \color{green}V\left(\mathbf{s}_{T}\right)&amp;=\log \int_{\mathcal{A}} \exp \left(r\left(\mathbf{s}_{T}, \mathbf{a}_{T}\right)\right) d \mathbf{a}_{T}\\ &amp;\approx\underset{\mathbb{A}}{softmax}\left(r\left(\mathbf{s}_{T}, \mathbf{a}_{T}\right)\right) \end{aligned}\] <p>At any time step t,</p> <div class="row justify-content-md-center"> <div class="col-7"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/SmartSelect_20220610-130406_Samsung_Notes-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/SmartSelect_20220610-130406_Samsung_Notes-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/SmartSelect_20220610-130406_Samsung_Notes-1400.webp"/> <img src="/assets/img/SmartSelect_20220610-130406_Samsung_Notes.jpg" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>The optimal policy that minimizes this objective at any time step t is given as :</p> \[\begin{aligned} \color{green}\pi^*\left(\mathbf{a}_{T} \mid \mathbf{s}_{T}\right)&amp;=\exp \left(Q\left(\mathbf{s}_{T}, \mathbf{a}_{T}\right)-V\left(\mathbf{s}_{T}\right)\right)\\ \color{green}Q\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)&amp;=r\left(\mathbf{s}_{t}, \mathbf{a}_{t}\right)+E_{\mathbf{s}_{t+1} \sim p\left(\mathbf{s}_{t+1} \mid \mathbf{s}_{t}, \mathbf{a}_{t}\right)}\left[V\left(\mathbf{s}_{t+1}\right)\right]\\ \color{green}V\left(\mathbf{s}_{T}\right)&amp;=\log \int_{\mathcal{A}} \exp \left(Q\left(\mathbf{s}_{T}, \mathbf{a}_{T}\right)\right) d \mathbf{a}_{T}\\ &amp;\approx\underset{\mathbb{A}}{softmax}\left(Q\left(\mathbf{s}_{T}, \mathbf{a}_{T}\right)\right) \end{aligned}\] <p>This means that, if we fix the dynamics and initial state distribution, and only allow the policy to change, we recover a Bellman backup operator that uses the expected value of the next state, rather than the optimistic estimate we saw in part 2 of the blog series. Thus we avoid the risk seeking behaviour / optimistic bellman backups via the control as inference framework.</p> <p>We will discuss how this framework is used practically in modern Deep RL alogorithms in the next part of this blog series.</p>]]></content><author><name>Vaisakh</name></author><summary type="html"><![CDATA[Deriving max entropy RL objective and soft bellman backup equations via variational inference in PGM]]></summary></entry><entry><title type="html">Meta Learning and MAML(Model Aganostic Meta Learning)</title><link href="https://vaisakh-shaj.github.io/blog/2018/MAML/" rel="alternate" type="text/html" title="Meta Learning and MAML(Model Aganostic Meta Learning)"/><published>2018-08-15T00:00:00+00:00</published><updated>2018-08-15T00:00:00+00:00</updated><id>https://vaisakh-shaj.github.io/blog/2018/MAML</id><content type="html" xml:base="https://vaisakh-shaj.github.io/blog/2018/MAML/"><![CDATA[<p>This blogpost will talk about Meta Learning and a very intuitive Meta Learning Algorithm namely Model Aganostic Meta Learning(MAML) and a couple of it’s variants.</p> <h1 id="meta-learning-learning-to-learn">Meta Learning (“Learning To Learn”)</h1> <p>Many problems of interest require rapid inference from small quantities of data. We should adopt learning strategies such that the single/few observations should result in abrupt shifts in behavior(single/few shot learning). When new data is encountered, the models must inefficiently relearn their parameters to adequately incorporate the new information without catastrophic interference.</p> <p>For example a robot designed to clean nuclear wastes, encounters a wide variety of tasks with many objects. It should be able to amortize their experience from previous learnt skills and improve data efficiency in acquiring new skills rather than Learning each skill from scratch.</p> <p>Another example would be malware vs clean classification task, where a classification engine has to adapt to the new malware variants being released each day. You would typically have few example per class for a new day(here the new task is classifying between malware and clean files encountered that particular day) and requires meta-learning for “few shot classification”. (This would be an interesting application of meta learning to try out)</p> <p><span style="color:green">Inspired from nature ?</span> This kind of flexible adaptation is a celebrated aspect of human learning (Jankowski et al., 2011), manifesting in settings ranging from motor control (Braun et al., 2009) to the acquisition of abstract concepts (Lake et al., 2015). Generating novel behavior based on inference from a few scraps of information – e.g., inferring the full range of applicability for a new word, heard in only one or two contexts – is something that has remained stubbornly beyond the reach of contemporary machine intelligence.</p> <p><span style="color:#FF0000"><strong>Why not Deep Learning ?</strong></span> In situations when only a few training examples are presented one-by-one, a straightforward gradient-based solution like Deep Neural Network is to completely re-learn the parameters from the data available at the moment. Such a strategy is prone to poor learning, and/or catastrophic interference. In view of these hazards, non-parametric methods are often considered to be better suited.</p> <p><strong>General Meta Learning Framework</strong></p> <p>Meta-learning generally refers to a scenario in which an agent learns at two levels, each associated with different time scales. <span style="color:#FF0000">Rapid learning/Task Specific Learning</span> occurs within a task, for example, when learning to accurately classify within a particular dataset. This learning is guided by knowledge accrued <strong>more gradually</strong> across tasks, which captures the way in which task structure varies across target domains. Given its two-tiered organization, this form of meta learning is often described as <span style="color:green"><strong>“learning to learn”.</strong></span> This task aganostic learning helps in quick adaptations to new tasks.</p> <p>This means during the meta-learning we need to provide the learning algorithm an information(encoding) about the task/context in some form, along with the training samples asossiated with each task. So <strong>how do we feed data to a meta-learner ?</strong></p> <div class="row mt-3"> <div class="col-sm mt-3 mt-md-0"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/gen-maml.PNG-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/gen-maml.PNG-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/gen-maml.PNG-1400.webp"/> <img src="/assets/img/gen-maml.PNG" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>During meta-learning we provide a support/context $D_{support}$ along with the test sample.</p> <p><span style="color:red"><strong>What is $D_{support}$?</strong></span>: $D_{support}$ can be defined as a set of $(x_i,y_i)$ tuples where $x_i$ is input/observation and $y_i$ is the output/reward. $D_{support}$ provides a context(information about task to be performed) with respect to the test sample. $D_{support}$ usually tends to have less number of samples(few shot) per class.</p> <h1 id="model-aganostic-meta-learning">Model Aganostic Meta Learning</h1> <p>The two key features of MAML are,</p> <p>1) it makes gradient based solutions good at “few shot learning”. 2) it is model aganostic in the sense that it can be applied to any learning algorithm/model(classification, regression and reinforcment learning) that uses a gradient descent based optimization.</p> <p><strong>Note</strong>: There are recent papers that extends maml for UnSupervised and Semi-Supervised tasks.</p> <p>As discussed earlier this meta learning procedure has 2 stages.</p> <div class="row mt-3"> <div class="col-sm mt-3 mt-md-0"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/maml.PNG-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/maml.PNG-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/maml.PNG-1400.webp"/> <img src="/assets/img/maml.PNG" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p>In the <strong>task specific update stage</strong>, corresponding to each task the model parameters are updated using the task specific dataset.</p> <p><strong>Update 1</strong> \[ \theta_i^{*}=\theta + \alpha\times \nabla_\theta L_i(\theta,y_i) \]</p> <p>Next is the <strong>meta update stage</strong>, where we try to find a <strong>genaralist</strong> structure among these tasks such that updated parameter is <span style="color:green"><strong>always closer to each of the task specific optimal parameter, $\theta_i$(See Figure 1).</strong></span> In effect the parameter gets updated in the meta update in such a manner that <span style="color:green"><strong>it is one(few) steps away from doing well at each one of the tasks.</strong></span> This is achieved by optimizing for the performance of $f_{\theta_i^*}$ with respect to $\theta$ across the tasks as follows:</p> <p><strong>Update 2</strong> \[ \begin{aligned} \theta = &amp; \theta + \beta\times\sum_i^NL_i(f_{\color{red}{\theta_i^*}},y_i)<br/> = &amp;\theta + \beta \nabla_\theta \sum_i^NL_i(f_{\color{red}{\theta + \alpha\times \nabla_\theta L_i(\theta,y_i)}},y_i) \end{aligned} \]</p> <p><strong>Another way of looking at MAML:</strong> <span style="color:Red">The meta optimization is performed over the model parameters $\theta$ but the objective is computed using the updated models $f_{\theta_i^*}$. Thus we update $\theta$ such that it learns to get a low classification error/high reward in the next step rather than this step.</span> <span style="color:green">This makes the model parameter $\theta$ to be more sensitive to changes in tasks such that a small changes in the parameter can produce large improvements in the direction of the task with respect to which it is tuned for.</span></p> <p><strong>Does MAML falls in the general meta learning framework ?:</strong> Yes. It does. The task specific learning happens in update 1 and meta-learning happens in update 2.</p> <p><strong>How to train?</strong> “You get good at what you practice”. Thus the training time protocol used is same as the testing time protocol, as in <a href="https://arxiv.org/pdf/1606.04080.pdf">O. Vinyal’s(2016)</a>. Split each data/demonstrations for each individual task into training and validation pair. Use one of these for Update 1(task specific learning) and the other for Update 2(meta-learning).</p> <p><strong>An Illustration</strong></p> <div class="row mt-3"> <div class="col-sm mt-3 mt-md-0"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/before-learning-min.gif-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/before-learning-min.gif-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/before-learning-min.gif-1400.webp"/> <img src="/assets/img/before-learning-min.gif" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <p><strong>Unsupervised Extension</strong></p> <p>Refer these <a href="https://arxiv.org/abs/1709.04905">One-Shot Visual Imitation Learning via Meta-Learning </a>, <a href="https://openreview.net/forum?id=r1n5Osurf">Semi-Supervised Few-Shot Learning with MAML</a>. <strong>I will write on these shortly.</strong></p> <h1 id="references">References</h1> <ol> <li>C. Finn et al. 2017 <a href="https://arxiv.org/pdf/1703.03400.pdf">Model-Agnostic Meta-Learning for Fast Adaptation of Deep Networks</a></li> <li>C. Finn et al. 2017 <a href="https://arxiv.org/abs/1709.04905">One-Shot Visual Imitation Learning via Meta-Learning </a></li> <li><a href="https://openreview.net/forum?id=r1n5Osurf">Semi-Supervised Few-Shot Learning with MAML</a></li> <li>O. Vinyals, 2016, <a href="https://arxiv.org/pdf/1606.04080.pdf">Matching Networks for One Shot Learning</a></li> </ol>]]></content><author><name></name></author><category term="MetaLearning"/><summary type="html"><![CDATA[This blogpost will talk about Meta Learning and a very intuitive Meta Learning Algorithm namely Model Aganostic Meta Learning(MAML) and a couple of it’s variants.]]></summary></entry><entry><title type="html">Kernel Methods in Machine Learning</title><link href="https://vaisakh-shaj.github.io/blog/2018/Kernel/" rel="alternate" type="text/html" title="Kernel Methods in Machine Learning"/><published>2018-07-07T00:00:00+00:00</published><updated>2018-07-07T00:00:00+00:00</updated><id>https://vaisakh-shaj.github.io/blog/2018/Kernel</id><content type="html" xml:base="https://vaisakh-shaj.github.io/blog/2018/Kernel/"><![CDATA[<p>This blog will talk about one of the most theoretically sound Machine Learning techniques called Kernel Methods which became popular along with its best known member the Support Vector Machines in the 1990s.</p> <p>In Kernel theory we assume that learning happens in the <strong>RKHS space</strong>(<span style="color:green">Nice space of functions for non-parametric statistics and machine learning</span>) and the theorem that forms the backbone for learning in RKHS is the <strong>Representer Theorem</strong>.</p> <p>Before scaring you guys with RKHS and theorems right from the beginning, let me explain two main properties of Kernel methods.</p> <p><u>Property 1</u>: Kernel Methods can be thought of as <span style="color:#FF0000">instance-based learners</span>: rather than learning some fixed set of parameters corresponding to the features of their inputs, they instead “remember” the \(i\)-th training example \(\mathbf{(x_i,y_i)}\) and learn for it a corresponding weight \(w_{i}\). This basically means functions(hyperplanes in SVM /basis functions in KPCA) learnt through Kernel Methods can be represented as a weighted linear combination of the training points and what the algorithm actually “learn” are these weights correspondning to each point. <a href="">Representer Theorem</a> provides explanation for this. Thus as per theorem the ** regularized risk functional**(basically the objective function of the optimization problem being solved) of any algorithm which is a member of the Kernel methods takes the following general form:</p> \[\hspace{1cm} \frac{1}{N}\sum_{i=1}^{N}C(y_i,f(x_i)) + \frac{\lambda}{2}\Omega(f)\] <p>\(\hspace{1cm} \Omega-\text{any monotonically increasing function}\) \(\hspace{1cm} C - \text{cost function}\) \(\hspace{1cm} f - \text{function that we intend to learn}\)</p> <p><u>Property 2</u>: Now comes the <span style="color:#FF0000">“Kernel Trick”</span>. Kernel Methods through Kernel Functions allow you to perform the learning as if it were projected to a higher dimensional space, by operating on its original space. <strong>You can <span style="color:blue">kernalize an algorithm</span> by reformulating it in such a manner that the computations dependent only on the inner products of the data points than actual data points which then can be replaced by a Kernel Function<span style="color:#FF0000">(following the property of RKHS)</span>.</strong></p> \[\hspace{2cm}\mathcal{k}(x,y) = \langle \phi(x),\phi(y) \rangle \hspace{1cm}\\] <ul> <li><span style="color:green">“Why is it nice?”</span>: Say you have a set of images of 32x32=1024 pixels. However this is not linearly separable. The option you have is to project it on to a higher dimensional space, lets say quadratic, $\mathcal{R}^{1024} \rightarrow \mathcal{R}^{1024x1024}$. Data manupulation in this space is highly expensive. Kernel functions allow us to do computations in the lower dimensional space, but effectively learning in the higher dimensional space.</li> </ul> <h2 id="few-algorithms">Few Algorithms</h2> <ol> <li> <p>Support Vector Machines</p> </li> <li> <p>Kernel Ridge Regression</p> </li> <li> <p>Kernel PCA</p> </li> </ol> <h2 id="appendix">Appendix</h2> <p><span style="color:green"><strong><u>Reproducing Kernel Hilbert Space(RKHS)</u></strong></span>: is a subspace of the <a href="https://en.wikipedia.org/wiki/Hilbert_space#Definition_and_illustration">Hilbert space</a> with respect to kernel \(k: \mathcal{X}\times\mathcal{X} \rightarrow \mathcal{R}\) constructed in the following manner.</p> <ul> <li>Let \(\mathcal{H'} = \\{ k(.x): x\epsilon \mathcal{X} \\}\) be set of kernel functions.</li> <li> <p>We construct a vector space \(\mathcal{H}\) using the linear combinations of all kernels functions in set \(\mathcal{H'}\), and any function \(f\epsilon \mathcal{H}\) can be represented as a linear combination of a subset of these kernel functions as \(f = \sum_{i=1}^n \alpha_ik(,x_i)\) for some \(n,x_i \epsilon \mathcal{X}\) and \(\alpha \epsilon \mathcal{R}\).</p> </li> <li>the inner product of \(f(.),g(.) \epsilon \mathcal{H}\) has the following definition: \(\langle f,g \rangle = \sum_{i=1}^n \sum_{j=1}^{n'} \alpha_i \beta_j k(x_i,x_j)\). (it can proven that this inner product is well defined)</li> <li> <p>this parculiar definition gives rise to the <strong>reproducing property of hilbert space</strong>. \(\langle f,k(.x) \rangle = \sum_{i=1}^n \alpha_i k(x,x_i) = f(x)\). This shows that kernel is a representer of evaluation(<strong>evaluation functional</strong>), analogous to Dirac delta functions.</p> </li> <li><span style="color:red">What is it’s significance?</span> : <span style="color:green">Enables Kernel Trick</span>. While learning in RKHS, inner-products in our computations can be replaced by kernels \(\langle \phi(x),\phi(y) \rangle = \langle k(.,x),k(.,y) \rangle=k(x,y)\), where \(\phi\) maps \(x\epsilon \mathcal{X}\) to an infinite dimensional space, \(\phi : x \rightarrow k(.,x)\epsilon\mathcal{H}\). This is particularly useful in cases where data is not linearly separable in $ \mathcal{X} $, where tranformations to higher dimensional spaces are necessary and kernel trick avoids us in making this explicit transformations.</li> </ul> <p><span style="color:green"><strong><u>Representer Theorem</u></strong></span>: states that a minimizer \(f^{*}\) of a regularized empirical risk function defined over a <strong>Reproducing Kernel Hilbert Space</strong> can be represented as a finite linear combination of kernel products evaluated on the input points in the training set data.</p> <ul> <li>Precise Definition: Let \(\Omega : [0,\infty) \rightarrow \mathcal{R}\) be a strictly a monotonically increasing function, by \(\mathcal{X}\) a set, and \(C : (\mathcal{X} × R^2)^N\) be an arbitrary loss function. Then any $ \mathcal{f} \epsilon $ RKHS \(\mathcal{F}\) minimizing the regularized risk functional</li> </ul> <p>\(\frac{1}{N}\sum_{i=1}^{N}C(y_i,f(x_i)) + \frac{\lambda}{2}\Omega(f)\) admits a representation of the form \(\mathcal{f}(.) = \sum_{i=1}^{N}\alpha_i k_{x_i}\).</p> <ul> <li><span style="color:red">What is it’s significance?</span>: <span style="color:green"><strong>Firstly</strong> it gave a genreric definition of optimization objective, that come under the umbrella of kernel methods.</span> <strong>Secondly</strong>, Representer theorems[Smola et. all 2011] are useful from a practical standpoint because they dramatically simplify the regularized empirical risk minimization problem. In most interesting applications, the search domain \(H_{k}\) for the minimization will be an infinite-dimensional subspace of \(L^{2}({\mathcal {X}})\), and therefore the search (as written) does not admit implementation on finite-memory and finite-precision computers. In contrast, the representation of \(f^{*}(\cdot )\) afforded by a representer theorem reduces the original (infinite-dimensional) minimization problem to a search for the optimal {\displaystyle n} n-dimensional vector of coefficients \(\alpha =( \alpha _{1},...,\alpha _{n})\in \mathbb {R} ^{n}\); \(\alpha\) can then be obtained by applying any standard function minimization algorithm. Consequently, <span style="color:green">representer theorems provide the theoretical basis for the reduction of the general machine learning problem to algorithms that can actually be implemented on computers in practice.</span></li> </ul> <p><strong>Tip</strong></p> <div class="row mt-3"> <div class="col-sm mt-3 mt-md-0"> <figure> <picture> <source class="responsive-img-srcset" media="(max-width: 480px)" srcset="/assets/img/functions.PNG-480.webp"/> <source class="responsive-img-srcset" media="(max-width: 800px)" srcset="/assets/img/functions.PNG-800.webp"/> <source class="responsive-img-srcset" media="(max-width: 1400px)" srcset="/assets/img/functions.PNG-1400.webp"/> <img src="/assets/img/functions.PNG" class="img-fluid rounded z-depth-1" width="auto" height="auto" onerror="this.onerror=null; $('.responsive-img-srcset').remove();"/> </picture> </figure> </div> </div> <h2 id="references">References</h2> <ol> <li><a href="https://people.cs.umass.edu/~domke/courses/sml2010/06kernels.pdf">Justin Domke - UMASS Notes</a></li> <li><a href="https://www.iist.ac.in/sites/default/files/people/RKHS.pdf">Sumitra.S.Nair - IIST Notes</a></li> <li><a href="http://nptel.ac.in/courses/117108048/37">NPTEL - P S Shastry -IISc</a></li> <li><a href="https://www.cs.cmu.edu/~epxing/Class/10715/lectures/lecture6.pdf">Eric Xing - CMU Slides</a></li> <li>Wikipedia</li> </ol> <h2 id="disclaimer">Disclaimer</h2> <p>Please feel free to contact me <a href="mailto:vaisakhs.shaj@gmail.com">vaisakhs.shaj@gmail.com</a> in case you find any errors/suggestions, I will correct those promptly. You may as well comment below.</p>]]></content><author><name></name></author><category term="KernelMethods"/><summary type="html"><![CDATA[This blog will talk about one of the most theoretically sound Machine Learning techniques called Kernel Methods which became popular along with its best known member the Support Vector Machines in the 1990s.]]></summary></entry></feed>